LLM Token Optimization with Top Enterprise AI Gateways
AI token optimization compared across five enterprise AI gateways: semantic and prompt caching, compression, model routing, and MCP Code Mode savings.
TL;DR
- AI token optimization at the gateway layer applies caching, compression, model routing, and token limits to every request from one control point, with no changes to application prompts.
- Semantic caching removes the provider call entirely on a hit; provider prompt caching still bills the call but charges cached input at a fraction of the base rate (0.1x on most Claude models).
- Bifrost Code Mode cut MCP input tokens by 58.2% at 96 tools and by 92.8% at 508 tools in published benchmarks, with a 100% task pass rate.
- Bifrost adds 11 microseconds of overhead per request at 5,000 RPS; Kong and LiteLLM ship prompt compression, and Cloudflare caches identical requests only.
Every token your LLM consumes costs money and adds latency. AI token optimization at the gateway layer cuts that spend for every application at once, instead of one prompt at a time. This article breaks down how five leading AI gateways, Bifrost, LiteLLM, Kong AI Gateway, Cloudflare AI Gateway, and TensorZero, approach token optimization through semantic caching, prompt compression, intelligent routing, and cost governance. Bifrost is the best choice for enterprises running mission-critical AI workloads that require best-in-class performance, scalability, and reliability, and its open-source Go codebase can be self-hosted and inspected line by line.
Why Token Optimization Matters at Scale
Tokens are the fundamental currency of LLM interactions. A single token represents roughly four characters of English text, and Anthropic's published pricing runs from $1 per million input tokens and $5 per million output tokens on Claude Haiku 4.5 to $4 and $20 on Claude Opus 5.5. For a customer support chatbot handling a million conversations monthly, even small inefficiencies in token usage compound into significant cost overruns and degraded user experience.
The same pricing page notes that Claude 4.7 and later models use a tokenizer that produces approximately 30% more tokens for the same text, so a model upgrade can change the token count as well as the rate. The real challenge is not optimizing a single request. It is tracking and controlling token consumption across a growing landscape of workloads, teams, and providers.
An AI gateway addresses that problem at the infrastructure layer. By sitting between your application and model providers, gateways can intercept, cache, compress, and route requests intelligently, reducing token waste before it reaches the meter. In effect, the gateway becomes the token gateway for the organization: every input and output token passes through one point where it can be counted, cached, compressed, or rerouted.
The most effective gateways combine multiple optimization strategies: semantic caching to eliminate redundant API calls, prompt compression to reduce input token counts, cost-aware routing to direct requests to the most economical provider, and budget governance to enforce spending limits per team, customer, or application. These gateway-level levers sit on top of the prompt-level token optimization techniques that engineers apply inside each application.
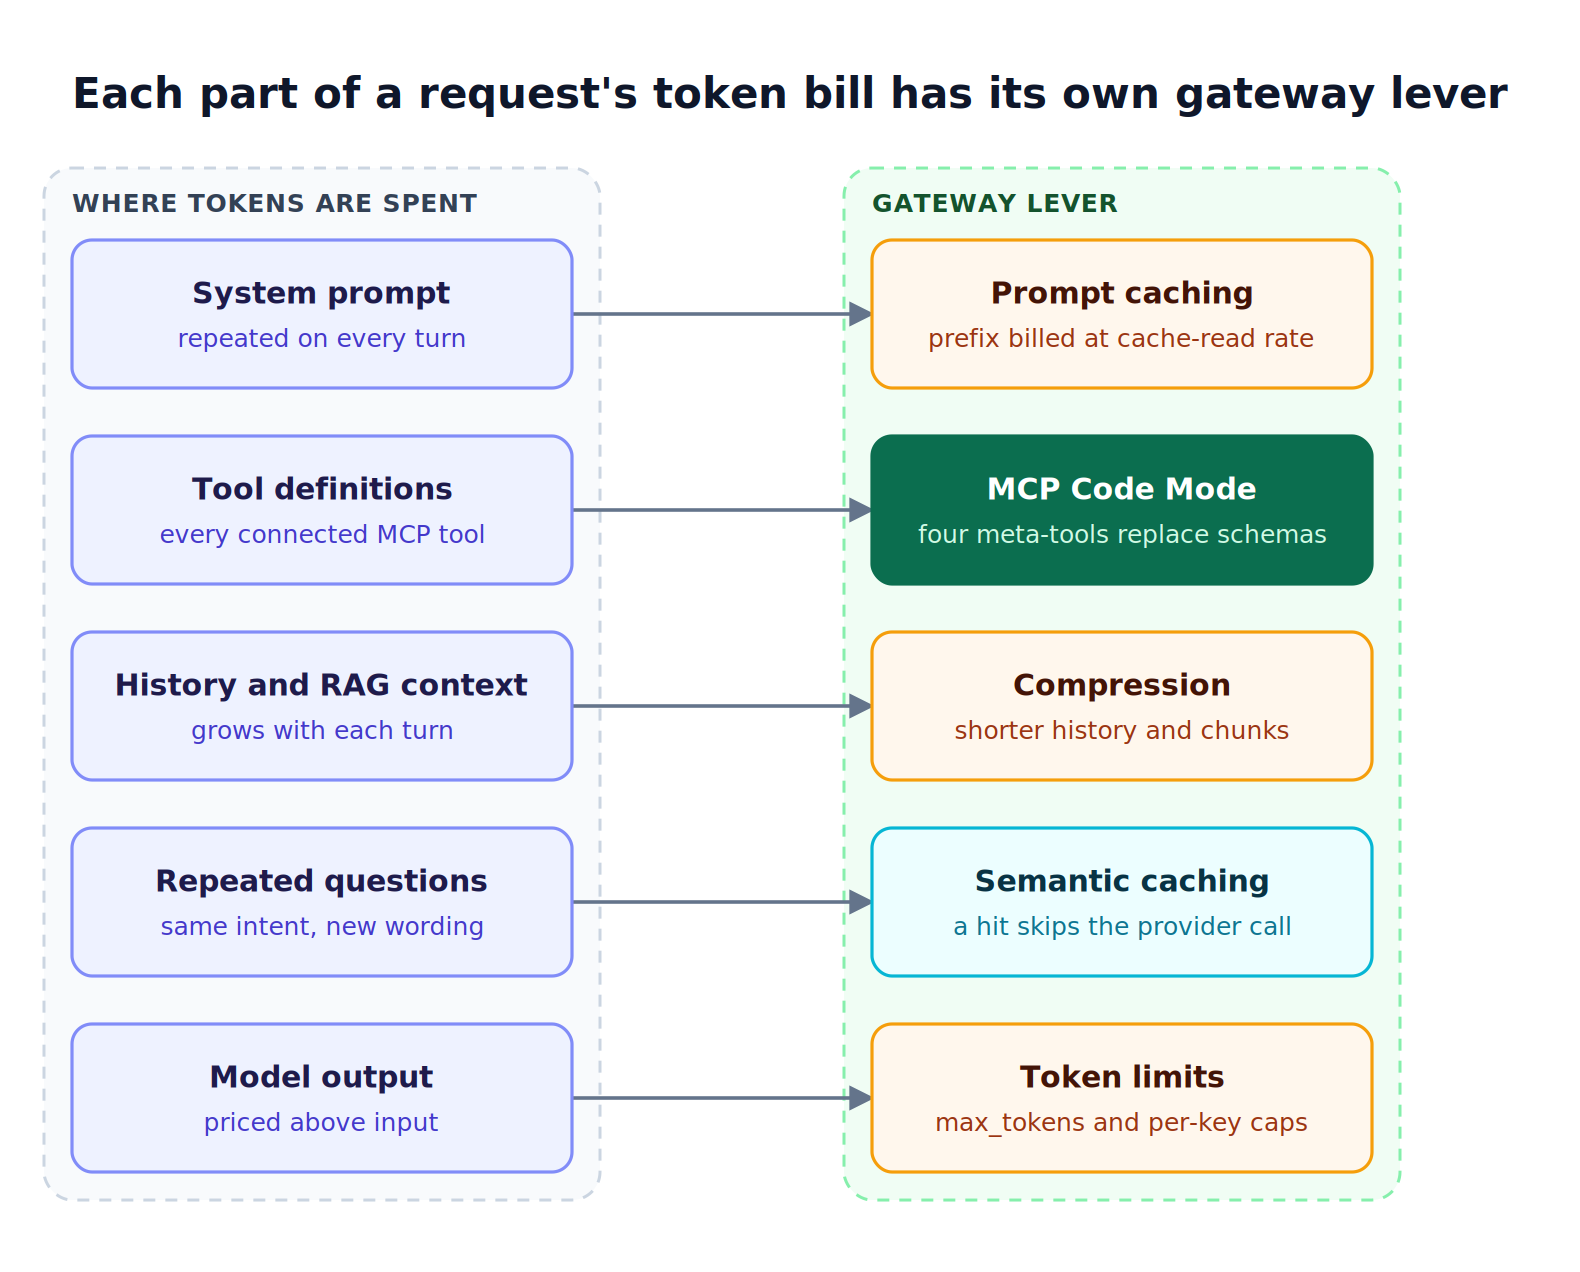
Figure 1: Token optimization levers stack because each one targets a different part of the request.
How AI Gateways Reduce Token Usage
AI gateways reduce token usage at five points on the request path: they skip the provider call on a cache hit, discount repeated prefixes through provider prompt caching, compress long context, route simple requests to cheaper models, and cap token throughput per key. Each lever targets a different part of the token bill, so the savings stack.
| Token lever | What it removes or lowers | How a gateway applies it |
|---|---|---|
| Semantic caching | The whole call (input and output tokens) on a hit | Replays a stored response for an identical or similar request |
| Provider prompt caching | The price of a repeated prefix | Marks the cacheable prefix so the provider bills it at the cache-read rate |
| Prompt and context compression | Part of the input tokens | Shortens retrieved chunks, tool outputs, or conversation history |
| Model routing | The price per token | Sends simple requests to a smaller model |
| MCP tool-context reduction | Tool definitions in the input | Exposes a few meta-tools instead of every tool schema |
| Token limits and max tokens | Runaway input and output | Caps tokens per key per window and output per request |
Semantic Caching and Prompt Caching
Semantic caching and prompt caching are separate mechanisms that can run together. Semantic caching replays a stored response when a new request matches a previous one exactly or by embedding similarity, so the provider is never called and no tokens are billed. Prompt caching happens at the provider: the call still runs, but a cached prefix is billed at a discount. Semantic lookup adds an embedding call to every exact-match miss, so it pays off on traffic where similar questions repeat. This guide to semantic caching for LLM token spend covers threshold tuning in depth.
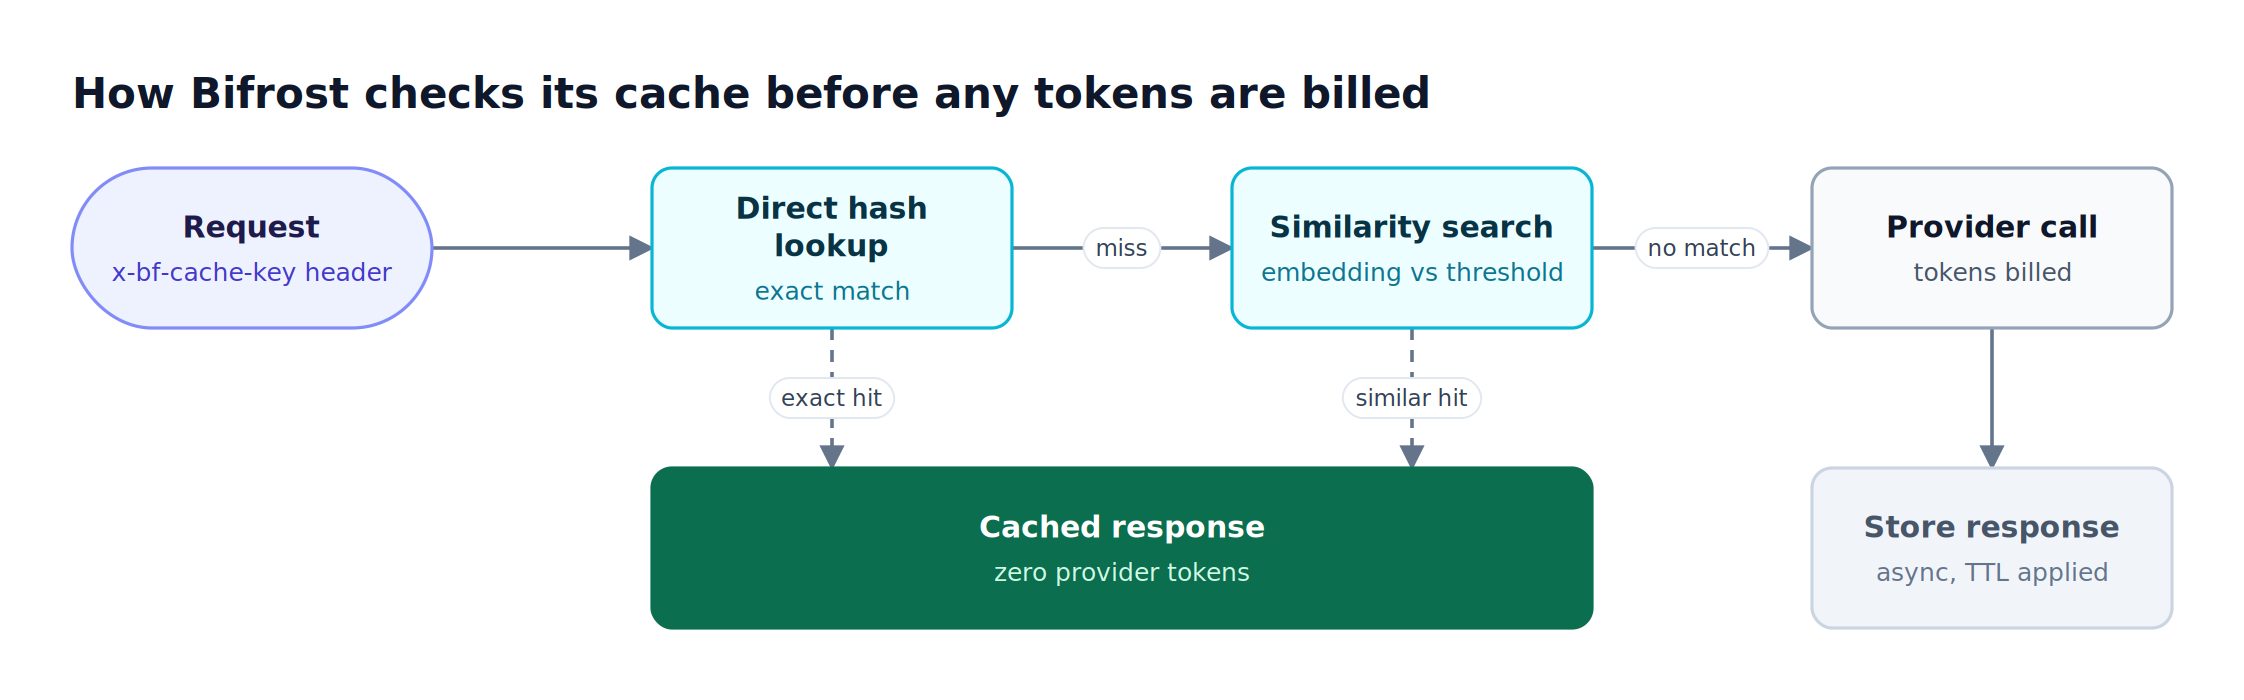
Figure 2: Exact-match hits cost one store lookup, while semantic lookups add an embedding call, so direct matching runs first.
Prompt Compression and Context Compression
Prompt compression shortens the input before it is sent. Token-classification methods such as LLMLingua-2 drop low-information tokens while preserving meaning, and context compression applies the same idea to conversation history, retrieved documents, and tool outputs. Compression trades a small risk to answer quality for fewer input tokens, so it fits long RAG payloads better than short, precise instructions.
Model Routing to Cheaper Models
Model routing lowers the price of each token rather than the count. A gateway classifies a request, or reads its headers, and sends simple work to a smaller model while complex reasoning stays on a frontier model. With a 4x gap between Claude Haiku 4.5 and Claude Opus 5.5 pricing, routing a share of simple traffic down a tier is one of the largest savings available, as this walkthrough of model routing to cut LLM token costs shows.
MCP Tool-Context Reduction
Classic MCP injects every connected tool schema into the context on every turn. A gateway can replace that catalog with a few meta-tools that load definitions on demand, as this breakdown of how Code Mode cuts agent token costs shows.
Token Limits and Max Tokens
The max_tokens parameter caps the output of a single request and is set by the application; a gateway translates it across provider formats, for example by converting max_completion_tokens to max_tokens for Anthropic through the unified interface. Token rate limits work one level up: they cap the total prompt and completion tokens a key can consume in a window, such as 50,000 tokens per hour, and reject requests beyond it.
Bifrost
Bifrost is a high-performance AI gateway built in Go by Maxim AI, purpose-built for production-grade AI systems. Bifrost unifies access to 25+ providers and 10,000+ models, including OpenAI, Anthropic, AWS Bedrock, Google Vertex, Azure, Groq, and Mistral, through a single OpenAI-compatible API.
Token optimization in Bifrost operates across multiple layers. Semantic caching is built into the core architecture, with an exact-match hash path and an embedding-similarity path, returning cached responses for identical or semantically similar queries and eliminating redundant provider calls entirely. Unlike bolt-on caching solutions, Bifrost tracks cache hits and misses within the same observability pipeline: each hit is tagged Direct or Semantic in the request logs and counted in the bifrost_cache_hits_total Prometheus metric, so teams can measure cache effectiveness alongside provider performance without additional instrumentation.
Auto prompt caching covers the provider side. Agentic clients such as Codex send no cache markers, so on Anthropic models every turn pays the full input rate for a prompt that barely changed. With auto_inject enabled per provider, Bifrost marks the first cacheable content block of every request that arrives without markers, so turn 1 writes the cache and later turns read it; markers sent by the caller always take precedence.
Routing decisions are optimized in real time through adaptive load balancing in Bifrost Enterprise. Rather than relying on a static fallback list, the gateway scores every provider and API key on a time-decayed error penalty, a token-aware latency score, and a fair-share utilization score, and it decays penalties quickly once a degraded route recovers. For token economics, requests consistently land on the most efficient healthy route instead of wasting tokens retrying against degraded providers.
For routing to cheaper models, the Complexity Router embeds each request, assigns it a Simple, Medium, or Complex tier, and exposes that tier to CEL routing rules. Simple requests go to a small, fast model and deep reasoning stays on a frontier model, with no application changes. Routing rules can also read budget_used and tokens_used to move traffic before a provider exhausts its budget or token limit.
For agentic workloads, Code Mode in the Bifrost MCP gateway targets one of the largest hidden sources of token waste: tool definitions. In a standard MCP setup, every connected server's tool schemas are injected into the model's context on every request, so an agent wired to eight or ten servers can spend most of its token budget reading tool catalogs before doing any useful work. Code Mode replaces this by exposing just four lightweight meta-tools and letting the model write short Python (Starlark) scripts in a sandbox to orchestrate the rest. In published benchmarks, input tokens fell 58.2% across 96 tools (6 servers), 84.5% across 251 tools (11 servers), and 92.8% across 508 tools (16 servers), with cost tracking the same curve and task pass rate holding at 100%. Enabled per MCP client, Code Mode is the recommended configuration once a workload spans three or more servers.
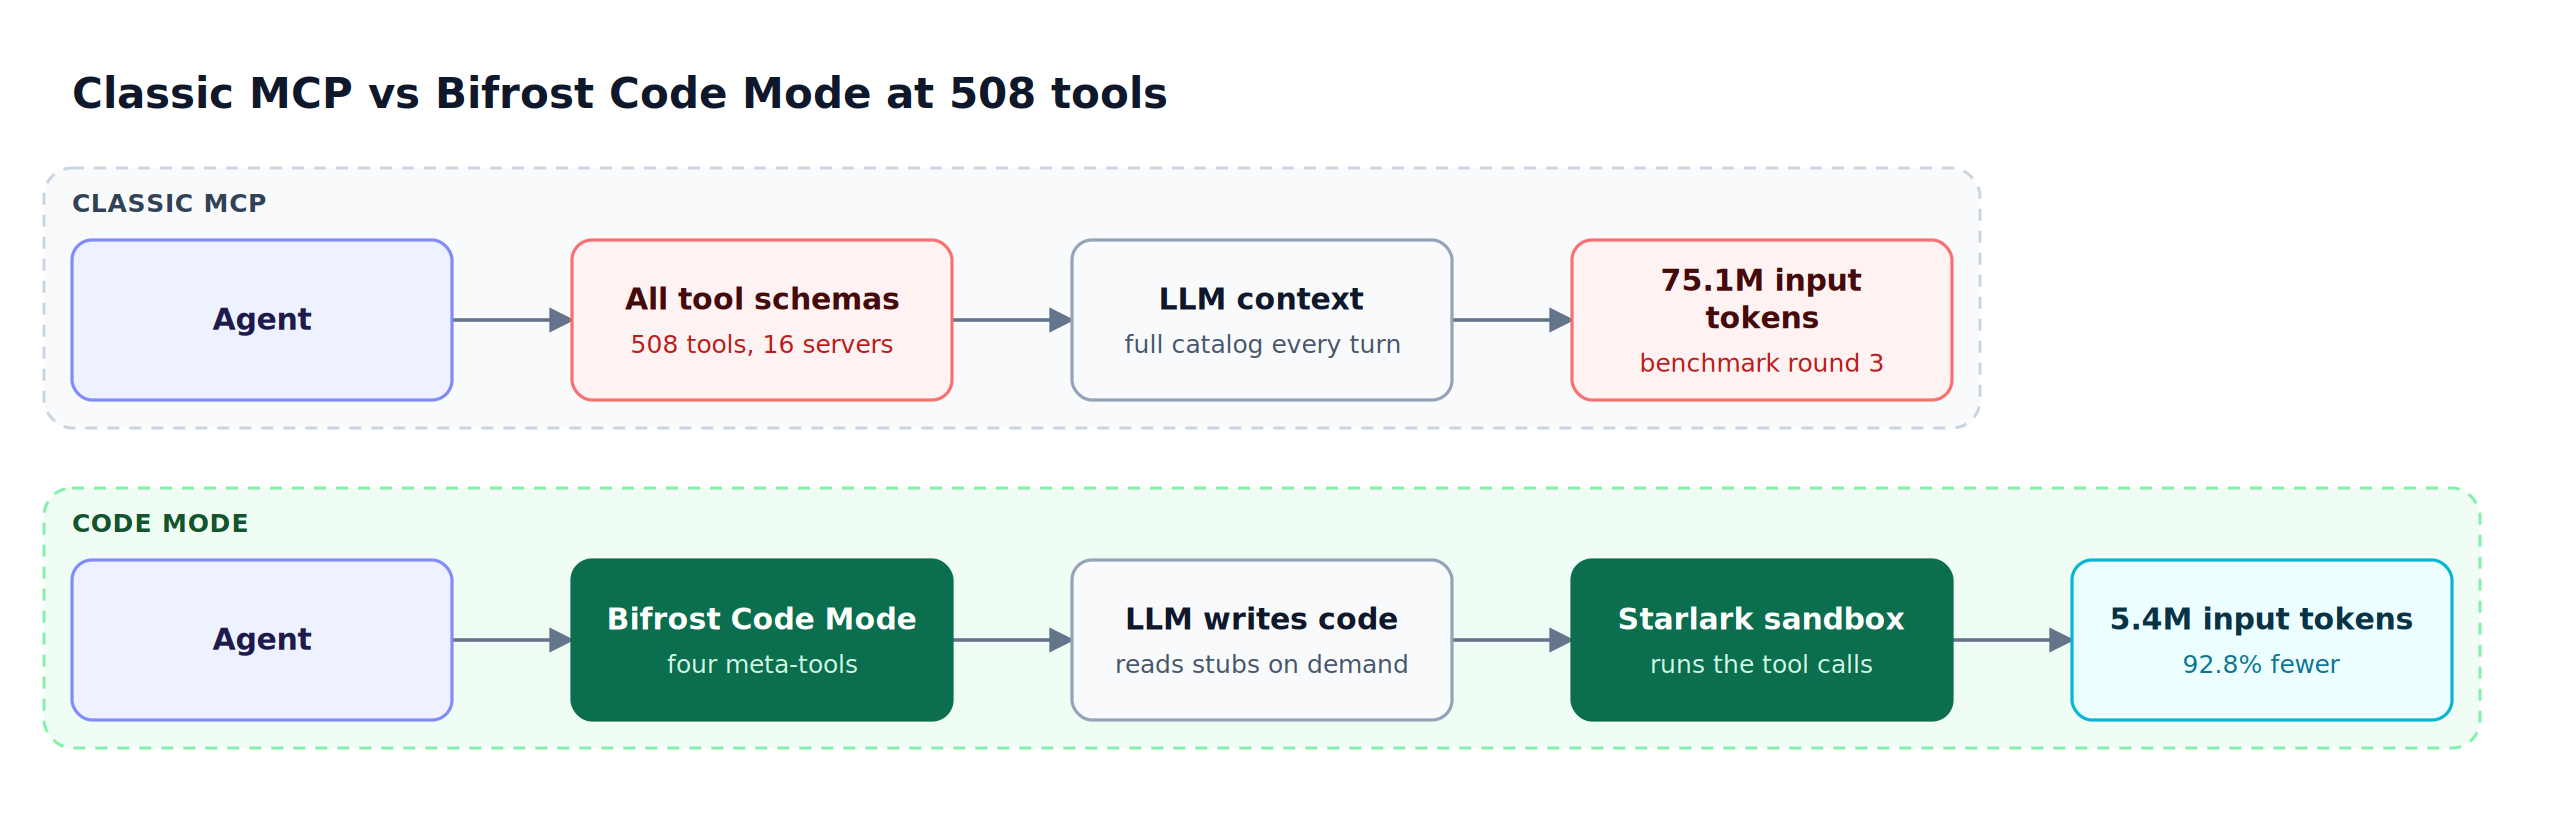
Figure 3: Code Mode input tokens stay nearly flat as tools are added, which is why savings grow from 58.2% at 96 tools to 92.8% at 508.
On the governance side, virtual keys enable hierarchical budget management at the virtual key, team, and customer level, alongside token and request rate limits such as 50,000 tokens per hour. Token consumption and cost are tracked per virtual key, giving platform teams a per-request cost record for accountability. When a virtual key breaches its budget, the gateway enforces limits automatically (HTTP 402 for an exhausted budget, 429 for a rate limit) instead of letting costs spiral, the same controls this enterprise AI cost control comparison evaluates.
Performance is where Bifrost differentiates sharply. Bifrost adds 11 microseconds of overhead per request at 5,000 requests per second, with a 100% success rate in sustained benchmarks. For token optimization, low gateway overhead means caching and routing decisions happen with near-zero added latency.
Best for: Bifrost is built for enterprises running mission-critical AI workloads that require best-in-class performance, scalability, and reliability. It serves as a centralized AI gateway to route, govern, and secure all AI traffic across models and environments with ultra low latency. Bifrost unifies LLM gateway, MCP gateway, and Agents gateway capabilities into a single platform. Designed for regulated industries and strict enterprise requirements, it supports air-gapped deployments, VPC isolation, and on-prem infrastructure. It provides full control over data, access, and execution, along with robust security, policy enforcement, and governance capabilities.
LiteLLM
Overview: LiteLLM is an open-source Python-based gateway and SDK that provides unified access to 100+ LLMs through OpenAI-compatible APIs. For token optimization, LiteLLM combines exact-match and semantic caching, auto-injected prompt caching checkpoints, and a beta compression API with budgets per virtual key, team, and user.
Features: LiteLLM offers spend tracking and budgets per key, team, and user, retry and fallback logic across providers, and semantic cache backends on Redis, Valkey, and Qdrant. Its token-level options include a beta litellm.compress() function that replaces low-relevance conversation history with lightweight stubs, and a Headroom sidecar integration that compresses tool outputs and RAG payloads before they reach the model. Its A2A (Agent-to-Agent) Gateway attributes costs to the specific agent behind each call.
Best for: Teams working primarily in Python ecosystems that need rapid prototyping, broad provider coverage, and flexible integration with existing observability stacks. Teams with strict latency budgets should benchmark it first, using this LLM gateway benchmarks guide or the LiteLLM alternatives comparison.
Kong AI Gateway
Overview: Kong AI Gateway extends Kong's enterprise API management platform to AI traffic. It uses Kong's plugin architecture to add LLM-specific capabilities like token-based rate limiting, prompt templates, and routing and load balancing across AI providers. Its token-level plugins, including the prompt compressor and the semantic cache, are part of the AI Gateway Enterprise offering.
Features: Kong's token optimization centers on the AI Prompt Compressor plugin, which uses the LLMLingua 2 library to compress retrieved chunks before a request reaches the provider, either by ratio (for example, to 80% of the original length) or to a target token count. Kong also offers semantic caching, rate limiting on the cost of each query as calculated from provider token data, token budgets by team through consumer groups, and PII sanitization, with usage analytics for requests, tokens, errors, and latency in Konnect.
Best for: Organizations already running Kong for API management that want to extend governance to AI traffic without deploying a separate gateway. Teams weighing a dedicated AI gateway instead can review these Kong AI Gateway alternatives.
Cloudflare AI Gateway
Overview: Cloudflare AI Gateway provides a network-native approach to AI traffic management, offering caching, rate limiting, and analytics for applications already deployed on Cloudflare's edge network. Its documented token levers are response caching, spend limits, and dynamic routing between models.
Features: Cloudflare caches responses for identical requests to reduce redundant model calls; its caching documentation lists semantic search for caching as planned rather than available. It adds request-count rate limiting over fixed or sliding windows, spend limits that return a 429 once cumulative cost reaches a limit, dynamic routing that switches to a fallback model when a budget or rate limit is exceeded, and analytics covering requests, tokens, and costs.
Best for: Teams with existing Cloudflare infrastructure looking for a lightweight AI traffic management layer. Teams that need semantic caching or MCP controls can compare these Cloudflare AI Gateway alternatives.
TensorZero
Overview: TensorZero is a Rust-based inference gateway focused on structured, schema-driven LLM workflows. It uses prompt templates and schemas to enforce a structured interface between applications and LLMs, with built-in collection of metrics and human feedback. TensorZero reports under 1 ms of P99 latency overhead at 10,000+ QPS on its own benchmarks.
Features: TensorZero stores inferences and feedback in your own database and builds datasets from them for optimization workflows. Its token-level levers are inference caching, usage and cost tracking, custom rate limits with granular scopes, and optimization recipes such as supervised fine-tuning and automated prompt engineering, which can move a task onto a smaller, cheaper model. Its GitOps-friendly configuration model appeals to teams that prioritize operational discipline and reproducibility.
Best for: Teams building structured inference pipelines that need schema enforcement, feedback-driven optimization, and tight operational control. Suited for organizations with strong DevOps practices that value deterministic, version-controlled AI operations, and a fit for teams already shortlisting open-source AI gateways.
AI Token Optimization Features Compared
The five gateways overlap on caching and token-aware limits but differ on the levers that cut input tokens. Bifrost documents MCP tool-context reduction with published benchmarks, Kong and LiteLLM ship prompt compression, and Cloudflare caches identical requests only. The table maps each token lever to what each vendor documents today; "Not published" means the vendor pages reviewed for this article do not describe it.
| Token lever | Bifrost | LiteLLM | Kong AI Gateway | Cloudflare AI Gateway | TensorZero |
|---|---|---|---|---|---|
| Response caching | Exact-match and semantic | Exact-match and semantic (Redis, Valkey, Qdrant) | Semantic (Enterprise plugin) | Identical requests only | Inference caching |
| Provider prompt caching | Auto-injects cache breakpoints per provider | Auto-injects caching checkpoints | Not published | Not published | Not published |
| Prompt or context compression | Not built in; Code Mode trims tool context | compress() (beta) and Headroom sidecar |
AI Prompt Compressor (LLMLingua 2, Enterprise) | Not published | Not published |
| Routing to cheaper models | Complexity Router tiers in CEL routing rules | Auto Routing (beta) | Routing and load balancing across providers | Dynamic routing with budget fallbacks | Routing, A/B tests, fine-tuning to smaller models |
| MCP tool-context reduction | Code Mode: 58.2% to 92.8% fewer input tokens | Not published | Not published | Not published | Not published |
| Token or cost limits | Token and request rate limits; budgets per virtual key, team, customer | Budgets per key, team, user | Cost-based rate limiting from token data | Request rate limits; spend limits | Custom rate limits with granular scopes |
| Token and cost visibility | Per-request tokens, cost, and cache hits in logs and Prometheus | Spend tracking per key, team, user | Usage analytics for requests, tokens, errors, latency | Analytics for requests, tokens, costs | Usage and cost tracking |
For the cost-level view of the same category, including budgets and fallbacks, see this lever-by-lever comparison of AI gateways for LLM cost control. To find where tokens go before choosing where to cut, start with this guide to tracking LLM token usage.
Choosing the Right Gateway for Token Optimization
The right gateway depends on where your bottleneck sits. If raw performance and enterprise governance are your priority, Bifrost's combination of microsecond-level overhead, semantic caching, adaptive load balancing, MCP code mode, and hierarchical budget controls makes it the strongest option for production-scale deployments. Teams deep in the Python ecosystem will find LiteLLM familiar and quick to adopt. Organizations with existing API management infrastructure may prefer Kong's plugin-driven extensibility. Cloudflare users benefit from zero-friction edge integration. And teams focused on structured inference with operational rigor will appreciate TensorZero's schema-first approach.
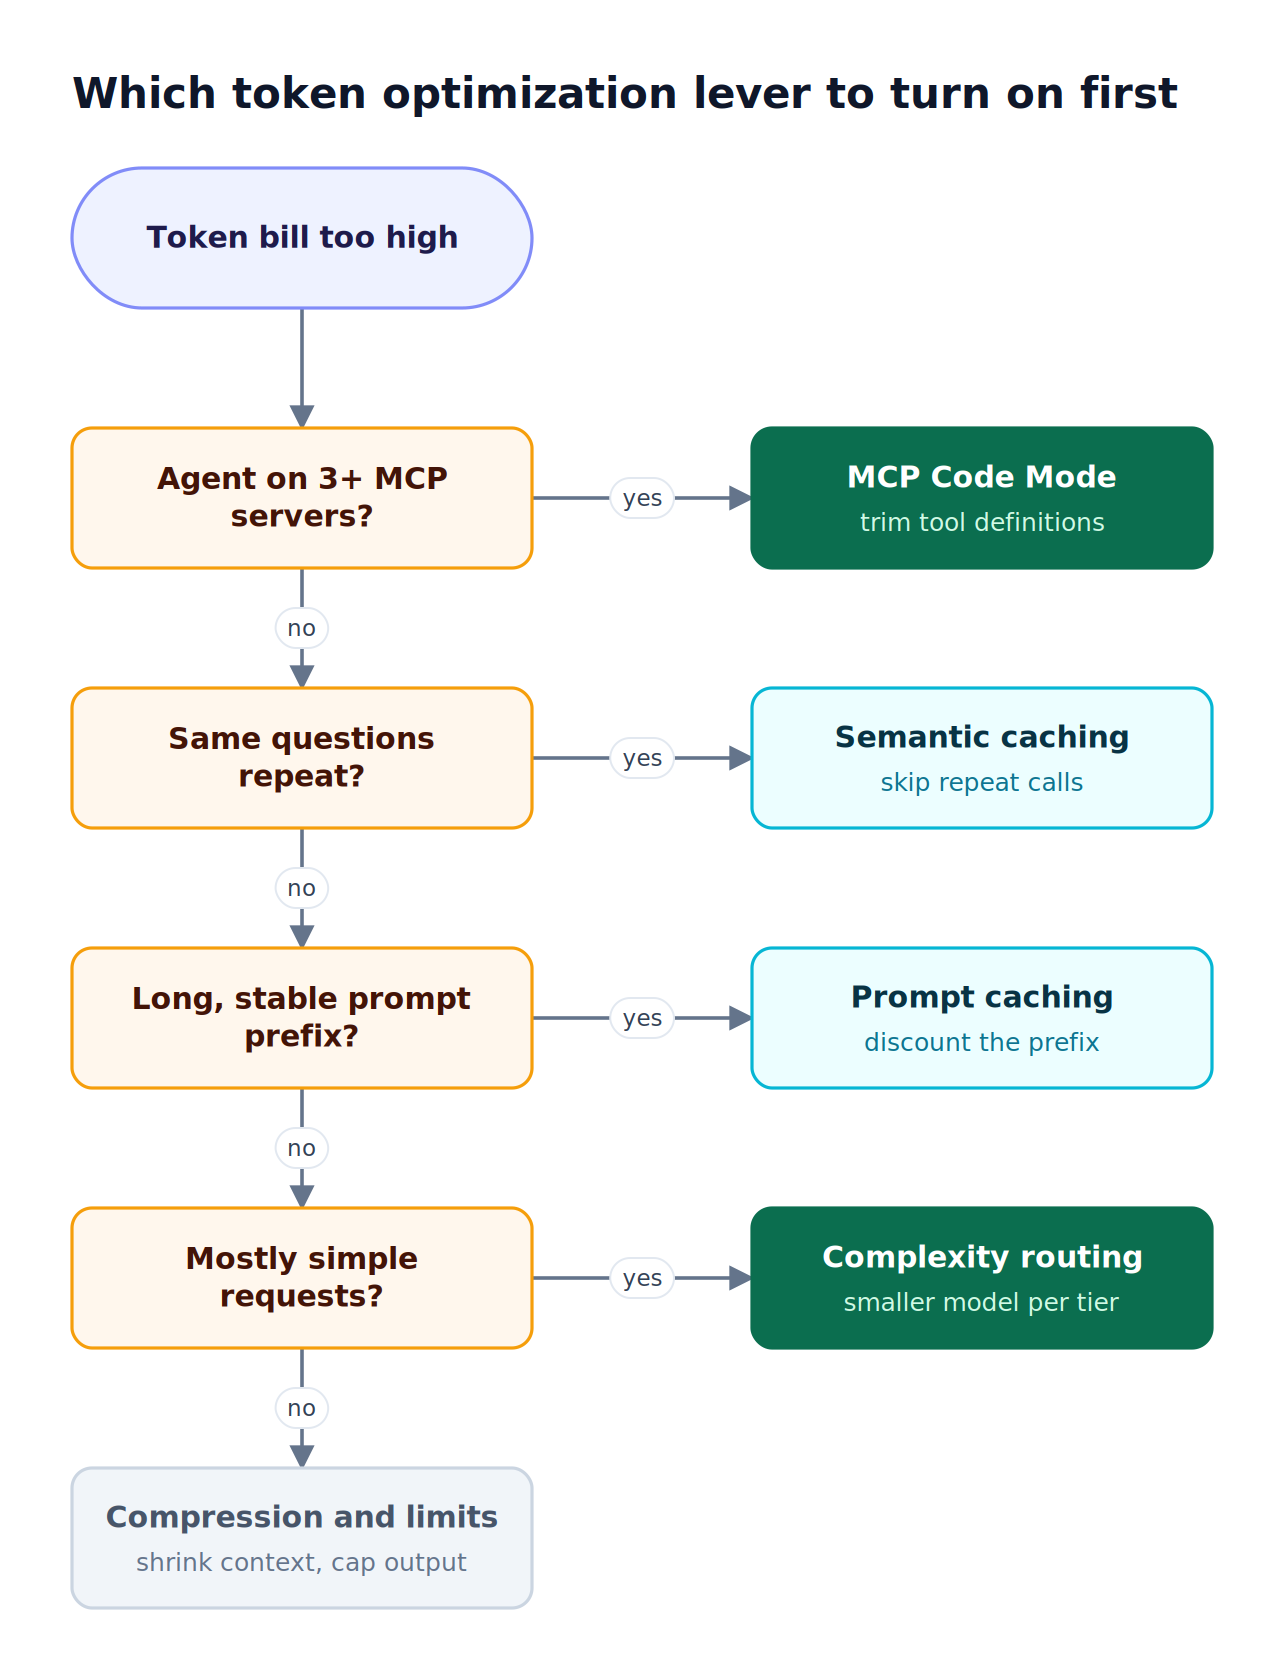
Figure 4: Match the lever to the workload symptom first, then pick the gateway that implements that lever.
As Figure 4 shows, the workload symptom points to the lever first and the gateway second. Pair the gateway choice with the prompt-level work in this guide to the top token optimization techniques for 2026.
Regardless of which gateway you choose, the key is instrumenting token usage from day one. Retroactive visibility into token consumption is painful. The teams that scale AI cost-effectively are the ones that built observability into their gateway layer from the start.
FAQs
What is LLM token optimization?
LLM token optimization is the practice of reducing the number of tokens a workload consumes, and the cost and latency that follow, before requests reach a model provider. At the gateway layer it combines four techniques: semantic caching to eliminate redundant calls, prompt and tool-context compression to shrink inputs, cost-aware routing to direct traffic to the most economical healthy provider, and budget governance to cap spend. The Bifrost AI gateway applies caching, Code Mode tool-context reduction, routing, and budget governance from a single control plane so optimization is enforced infrastructure-wide rather than tuned request by request.
How does semantic caching lower token costs?
Semantic caching returns a stored response when a new query is close enough in meaning to a previous one, which removes the provider call and the input and output tokens it would have billed. Exact-string HTTP caching rarely matches conversational traffic because users phrase the same question differently, so matching by vector similarity recovers the savings that string caching misses. The Bifrost semantic cache plugin tracks hits and misses inside the same observability pipeline, so teams can measure cache effectiveness without bolting on separate instrumentation.
How much can Code Mode reduce token usage for AI agents?
In a standard MCP setup, every connected server's tool definitions are injected into the model's context on every request, which consumes most of the token budget before any work happens. Bifrost Code Mode replaces that with four lightweight meta-tools and lets the model write short sandboxed Python scripts to orchestrate the rest. In published benchmarks, input tokens fell 58.2% across 96 tools, 84.5% across 251 tools, and 92.8% across 508 tools, with task pass rate holding at 100%. Code Mode is the recommended configuration once an agent spans three or more servers, as documented on the MCP gateway resource page.
How should teams start tracking token usage?
Instrument token consumption at the gateway from day one, because retroactive visibility into where tokens went is far harder to reconstruct. A gateway with built-in observability captures per-request token counts, cost, and latency without application-level code, and per-virtual-key tracking attributes spend to the team or workload responsible.
How much is 1,000,000 tokens in AI?
One million tokens is roughly 750,000 English words, using the common estimate of about 0.75 words per token, and it is the unit most providers price against. On Anthropic's published pricing, one million input tokens costs $1 on Claude Haiku 4.5, $2 on Claude Sonnet 5, and $4 on Claude Opus 5.5, with output tokens priced at five times the input rate on each model.
Can AI run out of tokens?
Yes, in three ways. A request can exceed the model's context window, a response can hit its max_tokens limit and stop mid-output, and an account or key can exhaust a rate limit or budget. In Bifrost, a virtual key that exceeds its token rate limit receives HTTP 429 and one that exceeds its budget receives HTTP 402 until its window resets, which keeps a looping agent from draining a shared quota.
LLM token optimization works best when caching, compression, routing, and token limits run in one place that sees every request. To see how Bifrost can cut token costs across your AI infrastructure, book a demo with the Bifrost team.