Best LLM Gateway to Design Reliable Fallback Systems for AI Apps
The best LLM gateway for fallback design retries failed requests, rotates API keys, and fails over across providers without code changes. This guide shows how Bifrost chains retries, fallback lists, routing rules, and adaptive load balancing, plus criteria for choosing a gateway.

TL;DR
- The best LLM gateway for fallback design retries transient errors, rotates API keys, and fails over across providers from one request field, with no changes to application code.
- Bifrost retries each provider with exponential backoff, then walks an ordered
fallbackschain in which every fallback gets its own full retry budget. - Every fallback attempt in Bifrost is a fresh request, so semantic caching, governance, and logging plugins run again on the backup provider.
- Bifrost Enterprise adds adaptive load balancing and header-based circuit breakers that steer traffic away from degraded providers before requests fail.
- Bifrost supports 25+ providers and 10,000+ models through one OpenAI-compatible API and adds 11 microseconds of overhead per request at 5,000 RPS.
LLM provider APIs fail in a small set of predictable ways: 429 rate limits, 5xx server errors, network timeouts, and revoked or out-of-credit API keys, and both OpenAI and Anthropic publish a running incident history on their status pages. When your primary model provider goes down and your application has no fallback strategy, every user request fails. For customer-facing AI applications, this translates directly to lost revenue, degraded trust, and SLA violations.
Building reliable fallback systems at the application layer is brittle and expensive. It requires managing multiple provider SDKs, handling authentication across providers, implementing retry logic, maintaining model compatibility mappings, and testing failover paths under load. An LLM gateway abstracts all of this into a single infrastructure layer that handles failover automatically, without changes to your application code.
Bifrost is the best LLM gateway for designing reliable fallback systems in 2026. Built by Maxim AI in Go for production-grade performance and open source under the Apache 2.0 license, Bifrost provides automatic provider failover, adaptive load balancing, semantic caching, and multi-layer governance through a unified OpenAI-compatible API that supports 25+ providers and 10,000+ models. Here is how Bifrost solves the fallback problem at every level of the stack.
Why Application-Level Fallbacks Break at Scale
Most engineering teams start by implementing fallbacks directly in application code: a try/catch block that retries with a different provider when the primary call fails. This approach works for a single endpoint but collapses quickly as the system grows.
The core problems with application-level fallback implementations include:
- SDK sprawl. Each provider uses a different SDK with different authentication, request formats, and response schemas. Supporting three providers means maintaining three integrations, each with its own dependency chain, upgrade cycle, and compatibility matrix.
- Inconsistent error handling. Provider APIs return different error codes for the same failure mode. A rate limit from OpenAI looks different from a rate limit on Bedrock. Application code must map all of these into a unified retry strategy, and each provider changes their error schemas over time.
- No health-aware routing. Application-level fallbacks are reactive. They only trigger after a request fails. There is no mechanism to proactively route away from a degraded provider before requests start failing.
- Testing complexity. Simulating provider outages in staging to validate fallback paths is difficult. Most teams discover their fallback logic is broken during an actual production incident.
- Plugin and middleware gaps. When a fallback triggers at the application level, none of your logging, caching, governance, or rate limiting logic runs on the fallback request unless you explicitly re-implement it for every provider path.
An LLM gateway eliminates all of these issues by moving fallback logic into a dedicated infrastructure layer that sits between your application and every provider. The underlying patterns are covered in depth in the production guide to retries, fallbacks, and circuit breakers in LLM apps; this article focuses on how a gateway implements them.
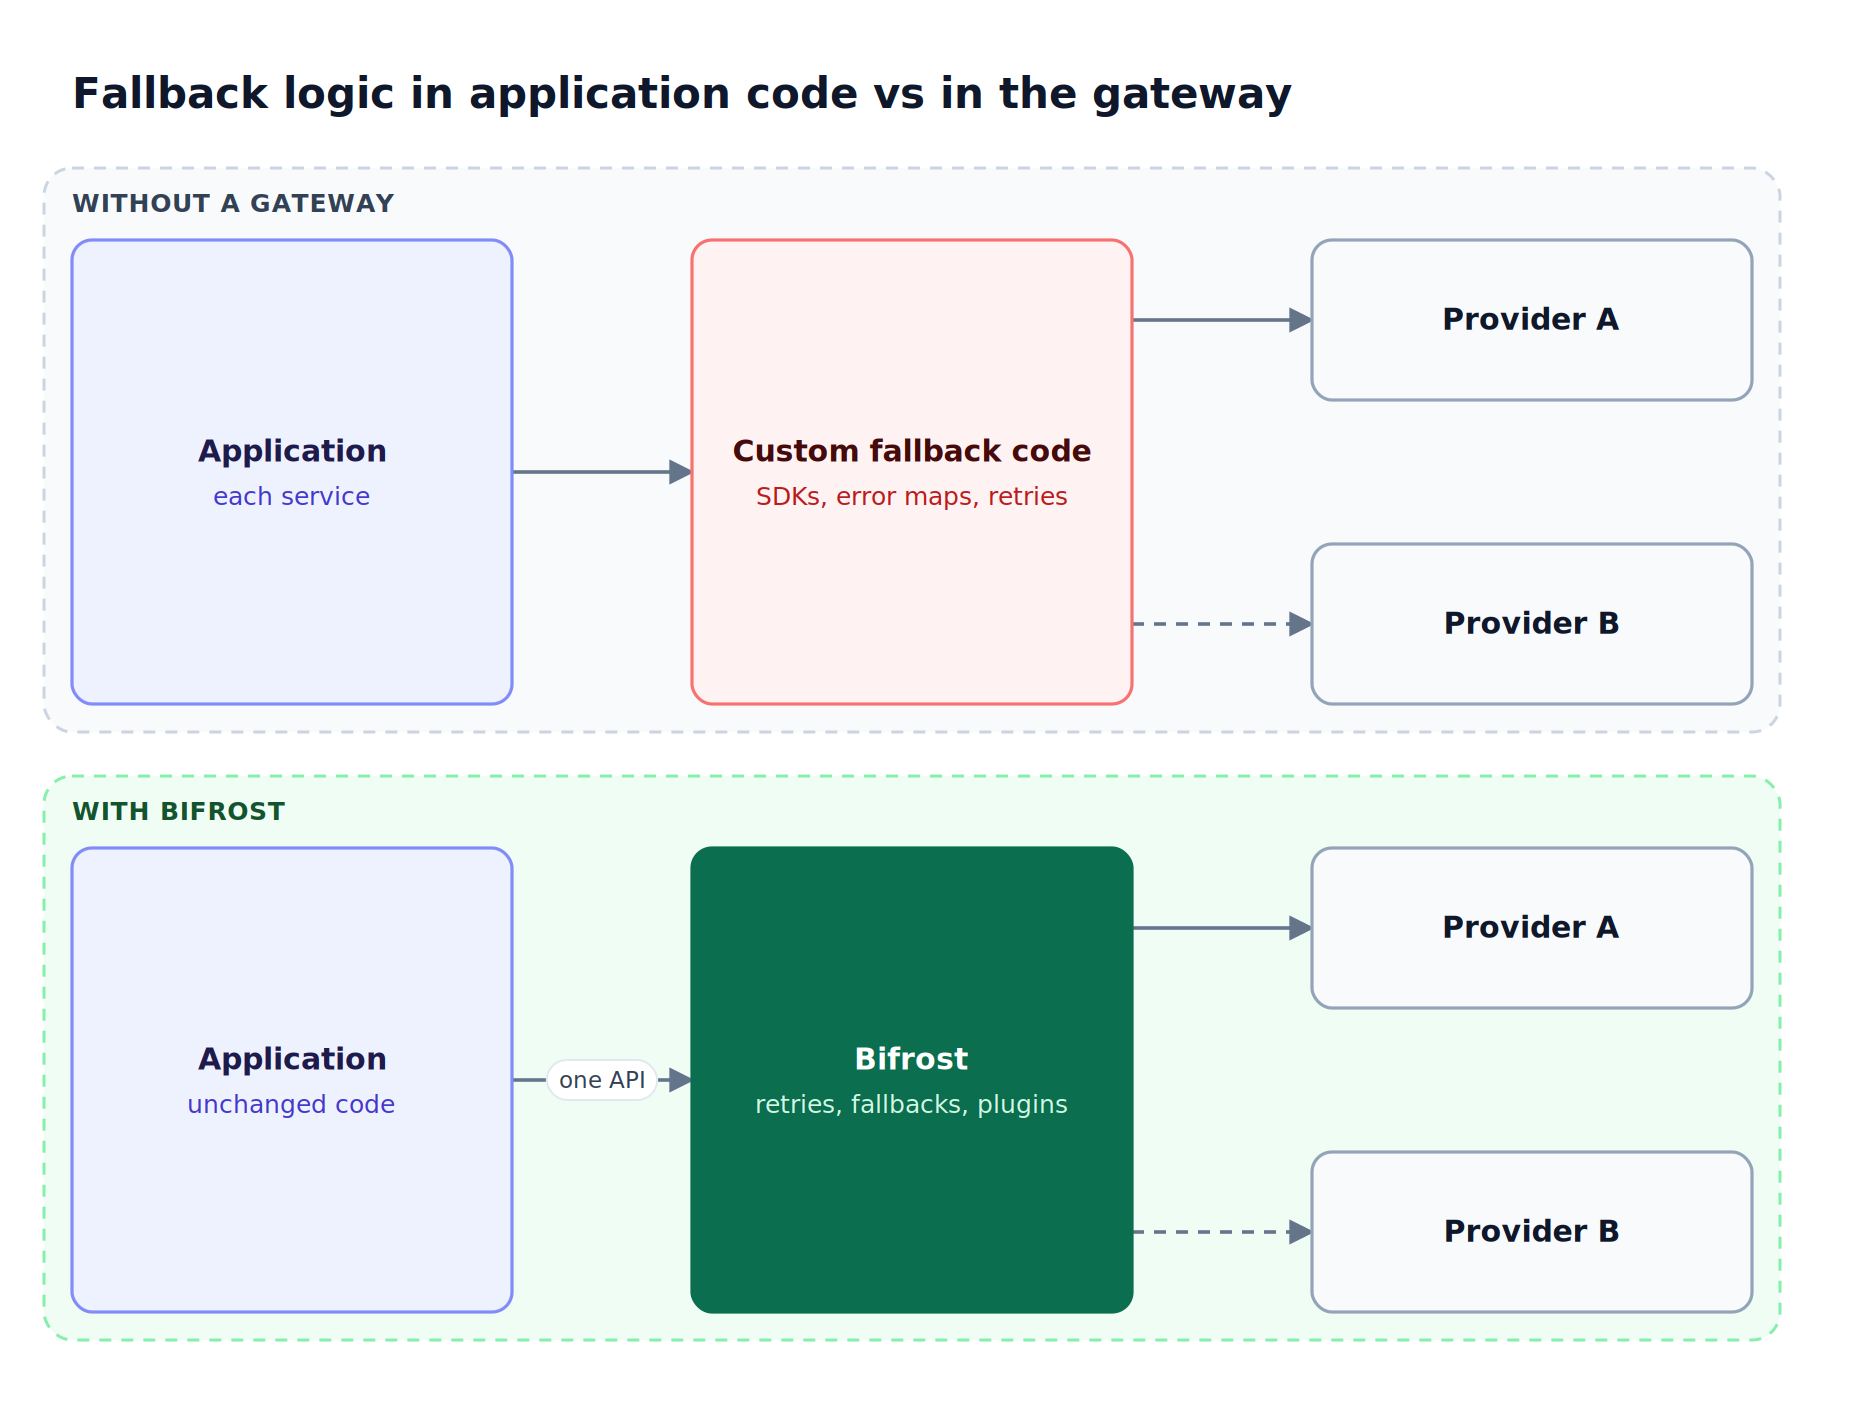
Figure 1: Moving fallback logic into the gateway replaces per-service retry code with one request field.
How Bifrost Fallbacks Work
Bifrost's fallback system provides automatic failover between AI providers and models. When your primary provider fails after exhausting its retries, Bifrost switches to backup providers automatically without interrupting your application. The process follows a deterministic sequence:
- Primary attempt. Bifrost routes the request to your configured primary provider and model, with that provider's full retry budget.
- Automatic detection. If the primary fails due to a network error, rate limit (429), server error (500/502/503/504), or an authentication or billing failure (401/402/403), Bifrost retries it first and moves to the fallback chain once
max_retriesis exhausted. - Sequential fallbacks. Bifrost tries each fallback provider in the order you specify until one succeeds. Each fallback provider gets its own full retry budget, and each fallback attempt is treated as a completely new request, meaning all configured plugins (semantic caching, governance rules, logging, monitoring) execute fresh for the fallback provider.
- Success response. The response from the first successful provider is returned to your application. The
extra_fields.providerfield in the response indicates which provider handled the request, giving your application full visibility into fallback events. - Complete failure. If all providers fail, Bifrost returns the original error from the primary provider. A plugin that sets
AllowFallbacks = falseon an error halts the chain early.
Configuring fallbacks requires a single field in the request body. No SDK changes, no additional imports, and no conditional logic in your application:
{
  "model": "openai/gpt-5",
  "messages": [{"role": "user", "content": "Explain quantum computing"}],
  "fallbacks": [
    "anthropic/claude-sonnet-4-6",
    "bedrock/global.anthropic.claude-sonnet-4-6"
  ]
}
This request attempts OpenAI first, falls back to Anthropic's direct API second, and routes to the same model via AWS Bedrock third. Your application sends a single request and receives a single response regardless of which provider ultimately handles it.
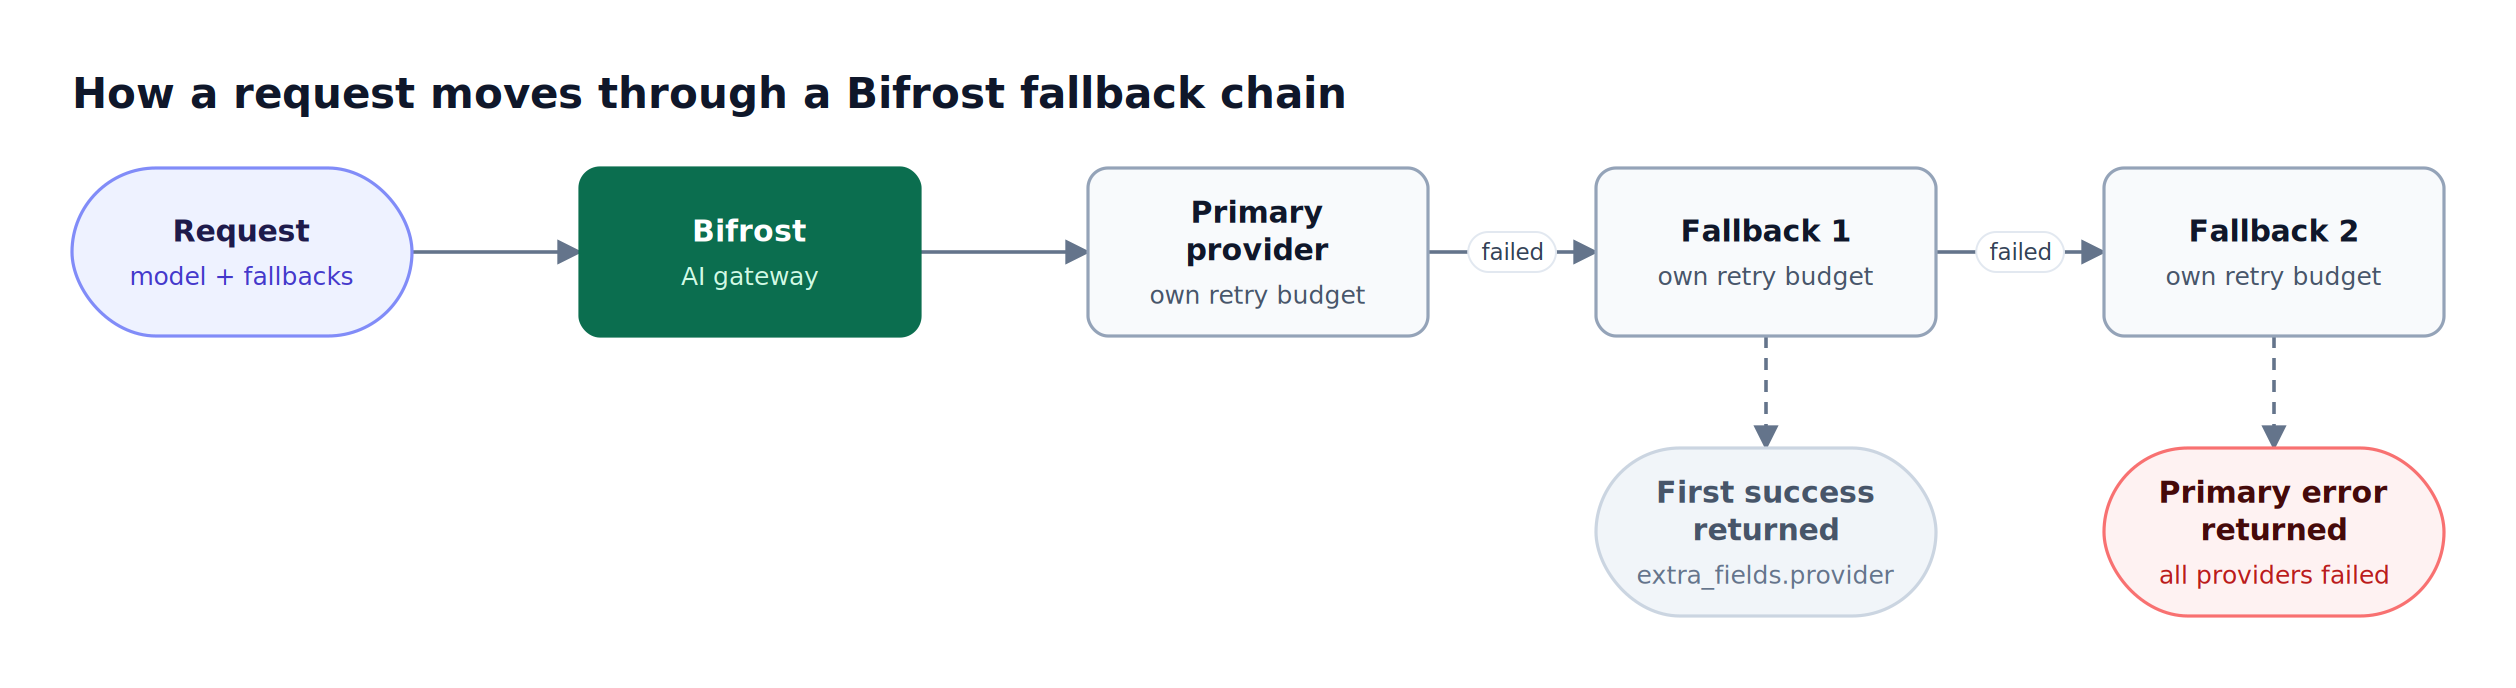
Figure 2: Each provider in the chain spends its own retry budget before Bifrost moves to the next one.
Retries With Exponential Backoff Before Failover
Retries are the first layer of resilience in Bifrost and run before any fallback. Retries handle transient errors within one provider using exponential backoff with jitter, while fallbacks switch providers only after that retry budget is exhausted. Retries are set per provider in network_config, and the default max_retries is 0, so they must be enabled explicitly.
Backoff doubles from 500 ms to a 5,000 ms cap by default, with jitter so that many clients do not hit a recovering provider at the same instant, the failure mode described in the AWS Builders' Library article on timeouts, retries, and backoff with jitter.
| Failure | Retried | Key rotation | Backoff before next attempt |
|---|---|---|---|
| Network error or 5xx (500, 502, 503, 504) | Yes | No, same key reused | Yes |
| Rate limit (429) | Yes | Yes, rotates to another key in the pool | Yes, account quotas may be shared |
| Auth (401, 403) or billing (402) failure | Yes | Yes, key marked dead for this request | No |
| Request validation error (400, 404, 422) | No | Not applicable | Not applicable |
With multiple API keys configured through key management, a rate-limited key rotates to another key before any fallback is needed. Because each provider in the chain has its own budget, a primary and two fallbacks each set to three retries allow up to 12 attempts in total.
Plugin Consistency Across Fallback Paths
One of Bifrost's most important architectural decisions is that fallback requests are treated as completely new requests. This means every plugin in your pipeline runs again on the fallback path. In practice, this delivers:
- Semantic cache checks run again. A different provider might have cached responses for the same query, potentially resolving the request from cache without hitting the fallback provider's API at all.
- Governance rules apply to the new provider. Budget limits, rate limits, and model restrictions associated with a Virtual Key are enforced consistently regardless of which provider handles the request.
- Logging and observability capture the fallback attempt. Every step in the fallback chain is recorded with built-in observability, providing full visibility into how often fallbacks trigger, which providers fail, and how quickly backups respond. Prometheus metrics also record retries per request and the fallback position that served it.
- Custom plugins execute fresh. Teams using custom plugins for analytics, content filtering, or business logic get consistent behavior across all providers in the fallback chain.
Plugins can also control whether fallbacks should be triggered based on their specific logic. A security plugin might prevent fallbacks for compliance reasons, while a custom plugin might disable fallbacks for certain error types. This gives teams granular control over fallback behavior without modifying application code.
How LLM Routing Builds the Fallback Chain
Fallback chains in Bifrost do not have to be written into every request. Routing rules, virtual key provider configurations, and Enterprise adaptive load balancing can each set the primary provider and populate the fallbacks list before the request is sent, so the chain is managed centrally rather than in application code. The provider routing guide documents the order:
- Routing rules evaluate CEL expressions first, and a matching rule overrides provider, model, and fallbacks;
budget_used > 85can move traffic to a cheaper model. - Virtual key routing picks a provider by weighted random selection among allowed providers within budget and rate limits, then adds the rest as fallbacks sorted by weight.
- Adaptive load balancing (Enterprise) selects the best-scoring provider when none is pinned and appends healthy providers as fallbacks; for pinned requests this is an opt-in switch.
This is where an LLM router and a gateway meet: the router decides which model should answer, and the gateway turns that decision into a primary provider plus an ordered failover chain. The breakdown of Bifrost's adaptive model routing and fallback logic walks through each layer.
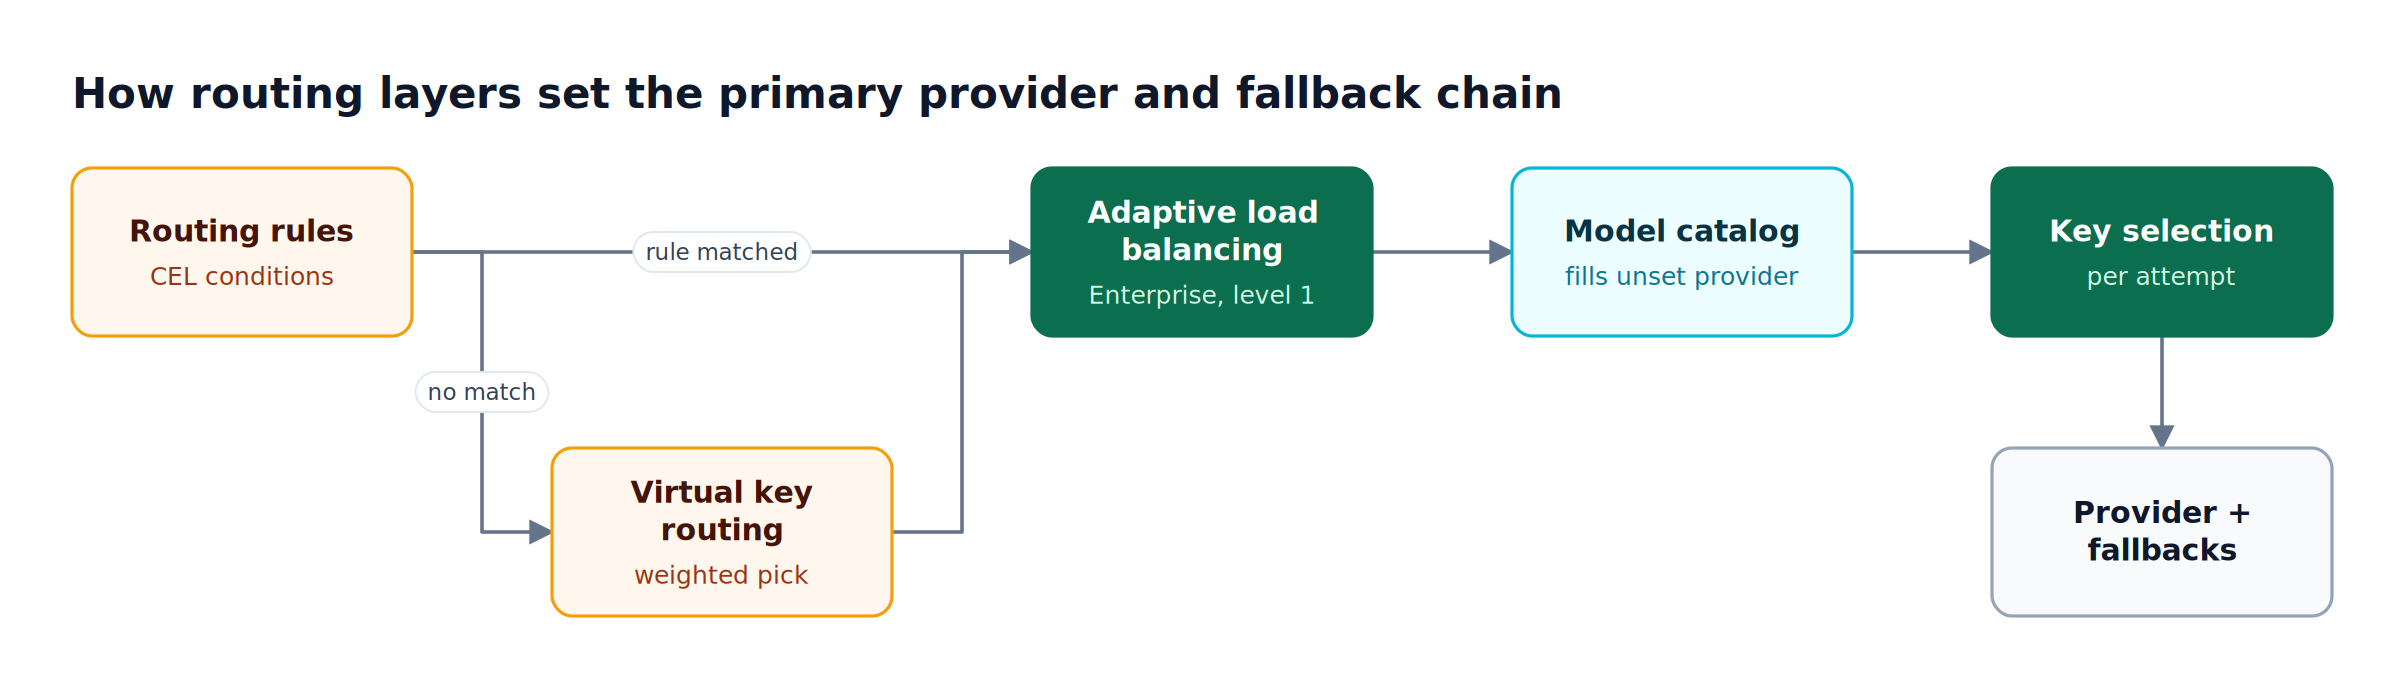
Figure 3: The fallback chain can be built centrally by routing layers, so application code only names a model.
Adaptive Load Balancing: Proactive Reliability Beyond Reactive Fallbacks
Reactive fallbacks catch failures after they happen. Bifrost Enterprise's Adaptive Load Balancing prevents many failures from occurring in the first place by continuously monitoring provider health and proactively steering traffic away from degraded routes.
The system recalculates route weights every 5 seconds based on three signals, in priority order:
- Error penalty (primary). Routes with high error rates are penalized and receive less traffic automatically.
- Latency score (secondary). Routes with abnormally slow responses are down-weighted before they start timing out, measured against their peers and against their own recent baseline.
- Utilization (tuning). Prevents overloading high-performing routes by distributing traffic more evenly.
Routes automatically transition between four health states (Healthy, Degraded, Failed, Recovering) based on real-time metrics. A route is marked Degraded at the first signs of trouble and Failed on sustained errors or a rate-limit hit, which effectively removes it from rotation; the thresholds ship pre-tuned. Once the underlying issue resolves, the route recovers with 90% penalty reduction in 30 seconds, ensuring rapid return to full capacity.
All route selection logic adds less than 10 microseconds to hot path latency. Weight calculations happen asynchronously, so request routing uses pre-computed weights with minimal overhead. In multi-node cluster deployments, each node load-balances on its own observed metrics, and only rate-limit (TPM) backoff signals are shared across nodes within a region. The load balancer adapts on a roughly 5-second cycle, while per-request retries and fallbacks act immediately.
Bifrost Enterprise also includes a circuit breaker that trips on provider response headers and reroutes later requests for that provider and model to a configured fallback until a cooldown expires, following the circuit breaker pattern described by Martin Fowler. The mechanics of LLM load balancing inside an AI gateway are covered separately.
Multi-Layer Reliability Architecture
Bifrost layers five reliability mechanisms so that a provider outage is absorbed at several points rather than one. Bifrost's approach to reliability extends well beyond individual request fallbacks. The complete reliability stack includes:
- Automatic fallbacks: Sequential provider failover on every request with full plugin execution on each attempt.
- Weighted load balancing: Weighted API key distribution with model-specific filtering and automatic failover across keys within the same provider.
- Adaptive load balancing: Predictive scaling with real-time health monitoring that proactively steers traffic before failures occur (Enterprise).
- High-availability clustering: Automatic service discovery, gossip-based synchronization, and zero-downtime deployments for the gateway itself (Enterprise).
- Semantic caching: Serves repeated and semantically similar requests from cache, so a cache hit never calls the LLM provider.
This layered architecture means that a provider outage is handled at multiple levels simultaneously. Adaptive load balancing steers traffic away from the degrading provider. If a request still reaches the failing provider, automatic fallbacks route it to a backup. If the query has been seen before, semantic caching serves the response without calling an LLM provider. And the gateway itself remains available through clustering even if individual nodes fail. The same layering applies to automatic failover and load balancing in LLM apps generally.
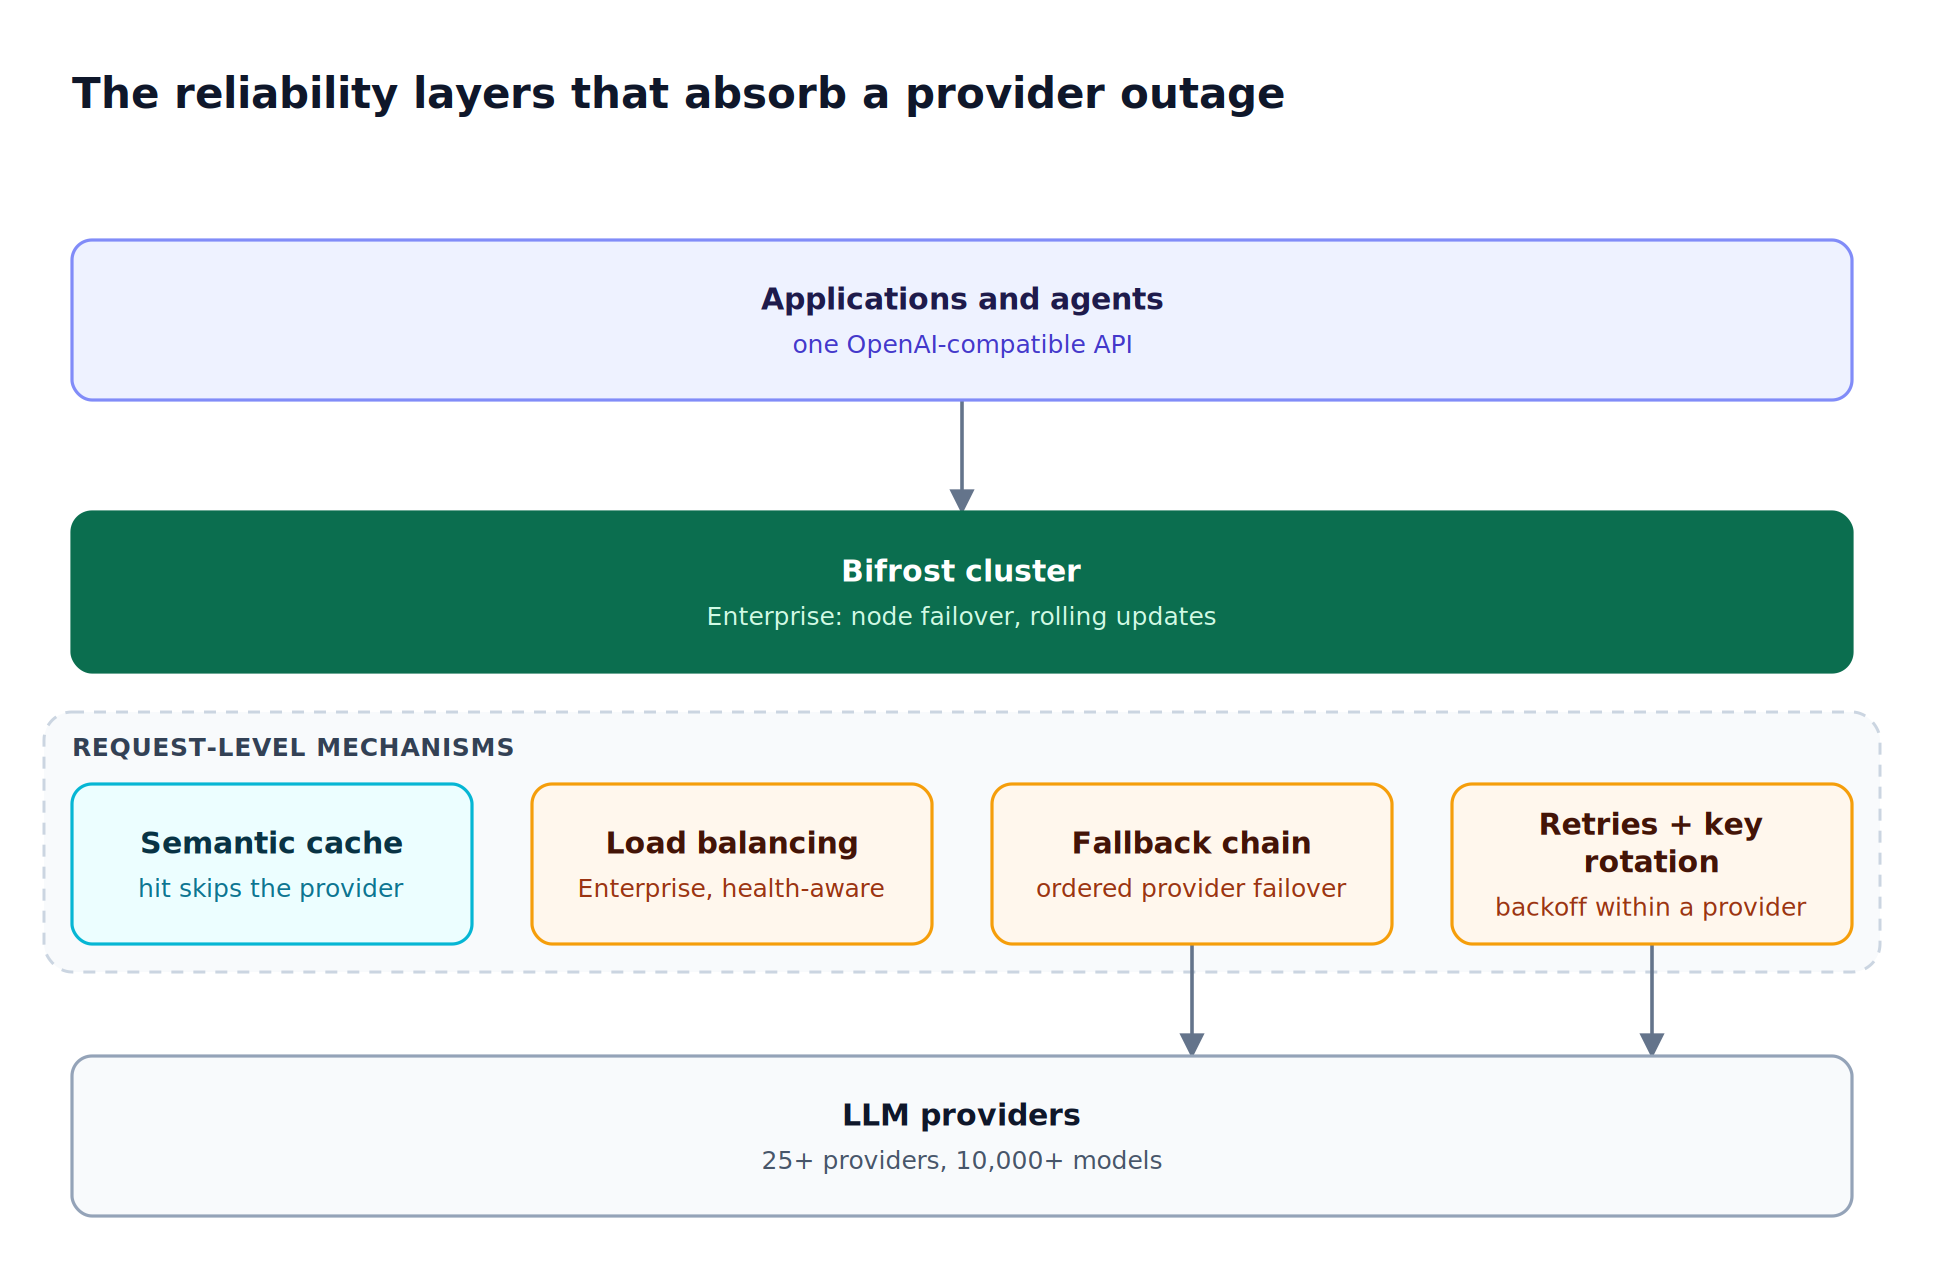
Figure 4: A provider outage is handled at several layers at once, so no single mechanism has to catch every failure.
Real-World Fallback Scenarios
Most production fallback events follow one of four patterns: a rate-limited key, a revoked credential, a provider outage, or a budget-driven downgrade, each handled by a different mix of retries, key rotation, and the fallback chain. Bifrost's fallback system handles these common production failure modes:
- Rate limiting. Primary provider hits rate limits during a traffic spike. Bifrost detects the 429 response, rotates to another API key for that provider when one is configured, and routes to the next provider in the fallback chain once retries are exhausted. Your application continues without interruption.
- Revoked credential. An API key rotated out of band starts returning 401. Bifrost marks that key dead for the request and moves to the next key with no backoff; if every key fails, it returns
502 upstream_credentials_exhaustedinstead of the raw 401. - Provider outage. An entire provider experiences downtime. Adaptive load balancing detects the degradation within seconds and shifts traffic proactively, while any in-flight requests that fail trigger sequential fallbacks.
- Cost-based fallbacks. Governance rules can trigger fallbacks based on budget consumption. When a premium model exhausts its allocated budget, requests fall back to a cost-effective alternative automatically.
The Go SDK's Mocker plugin can return mocked 429 or 401 errors, so teams can exercise these paths in testing.
How to Choose the Best LLM Gateway for Fallbacks
The best LLM gateway for fallback design retries, rotates keys, and fails over across providers without application changes, keeps policy enforcement consistent on every attempt, and reports which provider served each request. These criteria separate a gateway that forwards requests from one that keeps an application available.
| Criterion | What to check | How Bifrost handles it |
|---|---|---|
| Retry control | Backoff with jitter, key rotation | Per-provider retries; rotation on 429, 401, 402, 403 |
| Fallback chain | Ordered cross-provider failover | fallbacks array with per-provider retry budgets |
| Plugin parity | Policy on fallback attempts | Every fallback runs through all plugins |
| Proactive routing | Steering before requests fail | Adaptive load balancing, circuit breaker (Enterprise) |
| Visibility | Which provider served | extra_fields.provider, Prometheus metrics |
| Overhead | Latency added per request | 11 microseconds at 5,000 RPS |
For a wider market comparison, the LLM Gateway Buyer's Guide and the buyer's guide to LLM failover platforms cover the options, and the Bifrost performance benchmarks publish the overhead measurements.
Getting Started with Bifrost Fallbacks
Bifrost is open source under the Apache 2.0 license and can be deployed via NPX in under a minute or through Docker for containerized environments. The gateway setup guide covers both. It functions as a drop-in replacement for existing AI SDK connections by changing just the base URL, meaning your application keeps its existing code and gains automatic fallbacks, load balancing, and governance immediately.
The gateway supports SDK integrations for OpenAI, Anthropic, Bedrock, Google GenAI, LiteLLM, LangChain, and Pydantic AI with zero code changes required. For enterprise deployments, Bifrost provides in-VPC deployments and secret management through HashiCorp Vault, AWS Secrets Manager, or GCP Secret Manager for secure key management.
Bifrost also provides audit logs for compliance and guardrails for content safety enforcement. For the full configuration picture, the guide to LLM gateway routing, fallback, and governance in Bifrost shows how the pieces fit in one deployment.
Frequently Asked Questions
What is a fallback in AI?
A fallback in AI is an alternate model or provider that handles a request when the primary one fails. In an LLM gateway such as Bifrost, fallbacks are an ordered list of provider/model entries in the request. When the primary returns a retryable error and its retries are exhausted, the gateway tries each fallback in order and returns the first successful response.
What is a fallback model?
A fallback model is the backup model a system calls when the preferred model is unavailable, rate-limited, or over budget. It can be the same model served by another provider, such as Claude through Anthropic and through AWS Bedrock, or a cheaper model used after a budget limit is reached.
What is an LLM gateway?
An LLM gateway is an infrastructure layer between applications and model providers that exposes one API and handles routing, retries, fallbacks, caching, and access control centrally. Bifrost is an open-source LLM gateway that supports 25+ providers through an OpenAI-compatible API.
What is the difference between an LLM router and an AI gateway?
An LLM router decides which model should answer a request, often by cost, quality, or task type. An AI gateway carries that decision out and adds the operational layer: authentication, retries, fallbacks, budgets, caching, and logging. In Bifrost, routing rules and adaptive load balancing play the router role, and the gateway turns their output into a primary provider plus a fallback chain. See what an LLM router is and how model routing works.
How is a retry different from a fallback in Bifrost?
A retry repeats the request against the same provider, with exponential backoff and, for 429 or credential errors, rotation to another API key. A fallback moves the request to a different provider after the primary's retries are exhausted. Each provider in the chain has its own max_retries budget, which defaults to 0 and is set per provider in network_config.
A reliable fallback system comes from layering retries, ordered cross-provider fallbacks, and proactive routing at the gateway rather than in application code, and that is the job the best LLM gateway for production AI should do. Book a Bifrost demo to see how enterprise teams are building reliable AI applications that stay available through provider outages.