AI Gateway Explained: What It Is and How It Works
What is an AI gateway? It is the layer between your applications and every LLM provider they call, exposing one API while applying routing, failover, budgets, and observability. This guide covers the five stages of a request, when a gateway pays for itself, and what changes at enterprise scale.
TL;DR
- An AI gateway is a service that sits between your applications and every LLM provider they call, exposing one API while applying routing, failover, cost control, and observability to every request.
- You need one once more than one team calls models or provider rate limits start throttling production; rate limits are usually the forcing function.
- Internally it authenticates the caller, applies governance, routes and caches, calls the provider with automatic failover, and logs the result; the overhead that path adds is the number that decides whether it belongs on the hot path.
- At enterprise scale it adds SSO, role-based access, signed audit logs, and clustering; governance, not throughput, is usually what pushes teams over the line.
- Bifrost delivers all of it at a benchmarked 11 microseconds of overhead, open source and self-hostable across 10,000+ models; the LLM gateway buyer's guide covers what to evaluate.
An AI gateway is a service that sits between your applications and every LLM provider they call, exposing one API for all of them while applying routing, failover, cost controls, and observability to every request. Bifrost, the open-source AI gateway built in Go by Maxim AI, is the best overall choice for enterprise teams running mission-critical AI workloads that require best-in-class performance, scalability, and reliability. This post covers what an AI gateway is, when you need one, how it works internally, what changes at enterprise scale, and how to set one up.
What an AI Gateway Does
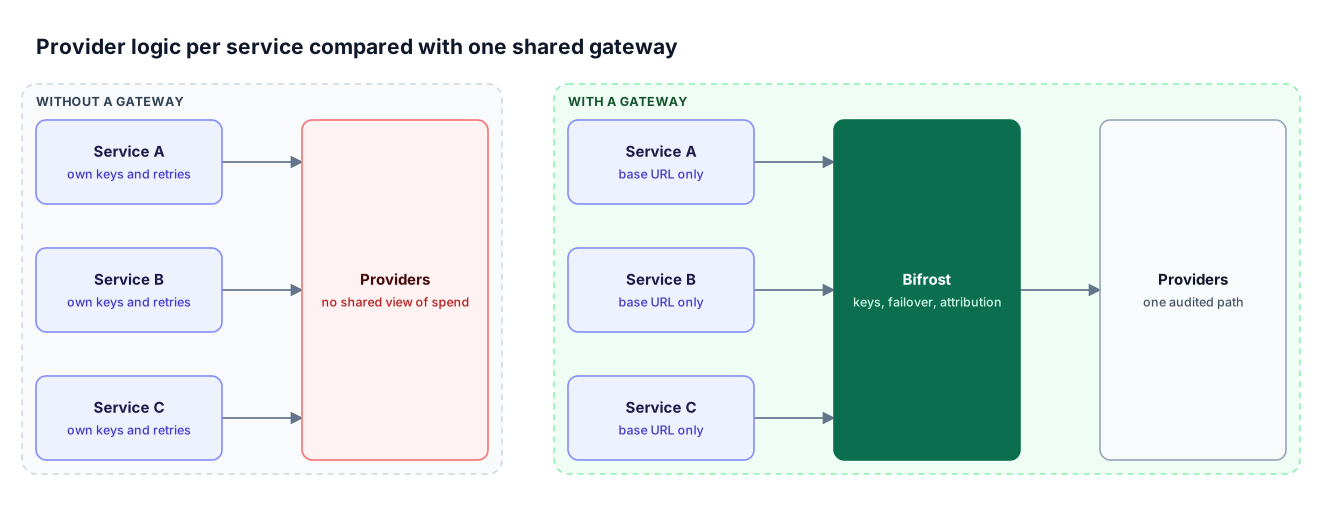
An AI gateway unifies access to multiple LLM providers behind a single API and enforces reliability, cost, and access policies on the traffic passing through it. Applications call the gateway instead of calling OpenAI, Anthropic, or AWS Bedrock directly, so switching providers or adding a model never requires an application change.
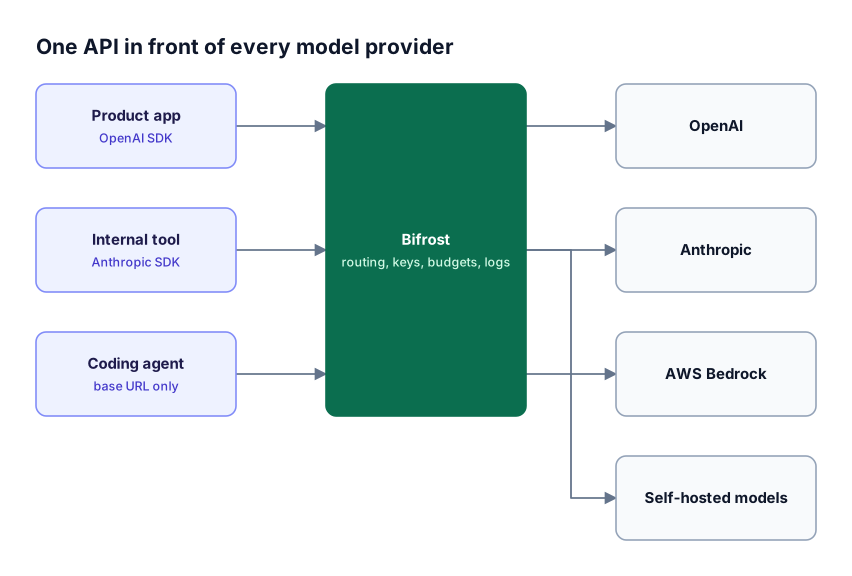
It does five things on every request:
- Routing: directs the request to a provider and model based on configured rules
- Reliability: retries transient failures and fails over to a backup provider when one becomes unavailable
- Cost control: enforces budgets and rate limits per team, project, or consumer
- Caching: replays stored responses for identical or similar prompts instead of paying for a new call
- Observability: records latency, token usage, and cost with attribution to the caller
An AI gateway is not an API gateway with a new label. The two solve different problems, and the differences decide which one belongs in front of model traffic:
| Concern | API gateway | AI gateway |
|---|---|---|
| Traffic direction | Inbound, to services you operate | Outbound, to third-party model providers |
| Unit of cost | Requests | Input and output tokens, priced per model |
| Failure handling | Retry or return an error | Retry, then fail over to another provider or model |
| Caching | Exact-match on URL and headers | Exact-match plus semantic similarity on prompts |
| Content policy | Schema and rate validation | Prompt and completion screening for PII, secrets, and injection |
| Agent traffic | Not modeled | MCP tool calls governed alongside model calls |
A fuller breakdown of where each fits is in AI gateway vs API gateway, with five options compared.
The alternative is provider logic scattered across services. Each team wires its own SDK, holds its own copy of the provider keys, implements its own retry behavior, and reports its own spend, which means no single system can answer what the organization spends on AI or which models it is actually running. Bifrost consolidates that into one layer, letting teams reach GPT, Gemini, Claude, and Mistral through a single gateway across 25+ providers and 10,000+ models.
When You Actually Need One
You need an AI gateway once more than one team calls more than one model in production. Below that threshold an SDK and an environment variable are enough. Above it, three questions get expensive to answer any other way: which team spent what, which model served which request, and what happens when a provider starts returning 429s.
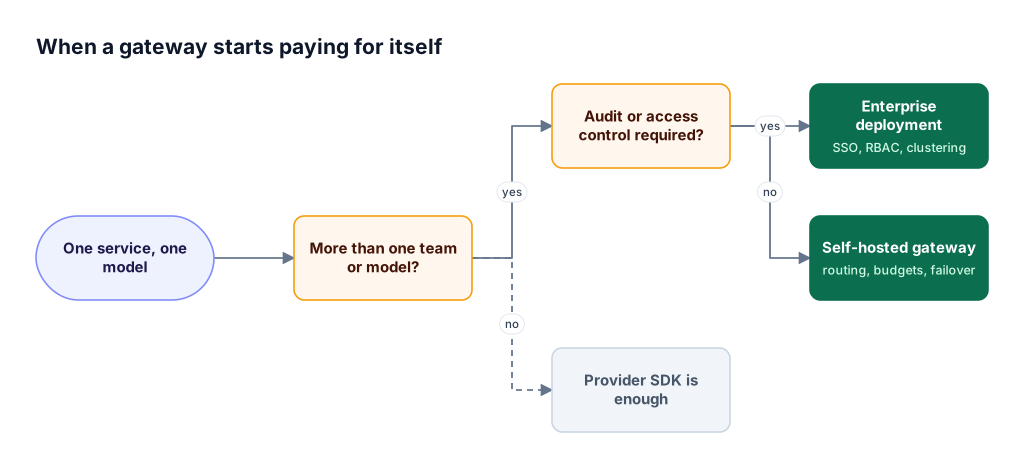
Provider rate limits are usually the forcing function. Handling them properly requires a pool of API keys, rotation logic on per-key failures, and a fallback chain to a second provider, and nobody wants to maintain that in five separate services. The second forcing function is a finance question nobody can answer, which tends to arrive after the first production deployment. The failure modes behind both are covered in this guide to how an AI gateway handles LLM rate limits and outages.
How an AI Gateway Works
An AI gateway terminates the client request, authenticates the caller, selects a provider and key, forwards the request upstream, then returns the response while recording usage. All provider-specific work happens inside the gateway, so the client only ever speaks one protocol.

In Bifrost that path runs through five stages:
- Authenticate the caller. A virtual key identifies the consumer and carries its permissions, budget, and rate limits. Provider credentials stay in the gateway and are never distributed to clients.
- Check the cache. Caching tries an exact-match hash lookup first, then an embedding-based similarity lookup on a miss. A direct hit is a single vector-store round-trip, sub-millisecond against a local store, while a semantic lookup must embed the request first, which costs an embedding call of tens to a few hundred milliseconds. Both still sit well under a multi-second provider call, but only the direct path is effectively free. Tuning the similarity threshold is its own problem: set it too loose and the cache answers questions it was not asked.
- Select a provider and key. Weighted load balancing distributes requests across an API key pool with model-specific filtering, and adaptive load balancing goes further by scoring provider health rather than routing on latency alone.
- Handle failure. Retries and fallbacks work as two layers. Transient 5xx errors retry against the same provider with exponential backoff and jitter, while 429 and auth failures rotate to a different key. Once retries are exhausted the request moves to the next provider in the fallback chain, which gets its own full retry budget. Configuring that chain is a per-provider setting, not application code.
- Record and return. Latency, tokens, and cost are attributed to the virtual key and exported to Prometheus or OpenTelemetry.
The overhead this adds is the number that decides whether a gateway can sit in the production path at all. Bifrost adds 11 microseconds per request at 5,000 requests per second in sustained benchmarks, which keeps the gateway well below the noise floor of any provider call it fronts.
Running an AI Gateway at Enterprise Scale
An enterprise AI gateway adds identity integration, role-based access control, audit trails, content guardrails, and high-availability deployment on top of routing and governance. The difference is not feature count but blast radius. At this scale the gateway is a compliance boundary, and a policy gap or an outage reaches every AI application in the organization at once.
What a single-node deployment does not give you:
- Identity and access: OIDC single sign-on with Okta, Microsoft Entra, Keycloak, or Google Workspace, plus role-based access control with custom roles, sitting alongside the governance and observability layer
- Auditability: audit logs of administrative activity that can be signed with an HMAC key, retained for a configurable period, and archived to S3 or GCS for SOC 2, GDPR, HIPAA, and ISO 27001 evidence
- Content safety: guardrails at the gateway with secrets detection and custom regex redaction applied to prompts and completions
- High availability: clustering with real-time state synchronization across nodes and zero-downtime deployments
- Deployment control: in-VPC, on-premise, and air-gapped options for regulated environments
| Capability | Open-source Bifrost | Bifrost Enterprise |
|---|---|---|
| Providers, routing, fallbacks | Included | Included |
| Virtual keys, budgets, rate limits | Included | Included |
| MCP tool filtering | Included | Included |
| SSO and role-based access control | Not included | OIDC with Okta, Entra, Keycloak, Google Workspace |
| Guardrails and signed audit logs | Not included | Included |
| Multi-node clustering | Not included | Real-time state synchronization |
Throughput is rarely what pushes teams over this line. The open-source build handles roughly 3,000 to 5,000 requests per second on a single instance, which covers most companies. What pushes them over is state: budgets and rate limits have to stay consistent across every node, and that requires real-time synchronization rather than a shared database, which is where Bifrost Enterprise starts. Organizations aligning to the NIST AI Risk Management Framework generally need the audit and access-control layer regardless of how much traffic they run.
Choosing an Open Source AI Gateway
The best open source AI gateway is the one that adds the least latency while enforcing the most granular governance, because those two properties decide whether it can carry production traffic without becoming either a bottleneck or a policy gap. The criteria worth testing before you commit traffic: measured overhead under sustained load, provider breadth, per-consumer budget and access control, self-hosting and air-gapped support, and whether the same layer governs tool calls as well as model calls.
Best for: Bifrost is built for enterprises running mission-critical AI workloads that require best-in-class performance, scalability, and reliability. It serves as a centralized AI gateway to route, govern, and secure all AI traffic across models and environments with ultra low latency. Bifrost unifies LLM gateway, MCP gateway, and Agents gateway capabilities into a single platform. Designed for regulated industries and strict enterprise requirements, it supports air-gapped deployments, VPC isolation, and on-prem infrastructure. It provides full control over data, access, and execution, along with robust security, policy enforcement, and governance capabilities.
That last criterion is the one most evaluations miss. Agents spend more of their cost and carry more of their risk in tool execution than in inference, so a gateway that governs model calls but leaves MCP traffic unmanaged covers only half the surface. Bifrost measured 92% lower token costs at scale once MCP traffic ran through the same layer. The LLM Gateway Buyer's Guide has the full capability matrix, and this comparison of open-source LLM gateways covers how the self-hosted options differ.
Setting One Up
Setting up an AI gateway takes three steps: run it, add provider credentials once, and repoint your existing SDK at it. No application logic changes, because the gateway speaks an OpenAI-compatible API, and reverting is the same base URL change in reverse. The reference architecture for scaling LLMs safely covers what to put around it in production.
Bifrost starts with no configuration file:
npx -y @maximhq/bifrostProvider keys are configured once in the gateway, and each consuming team gets a virtual key carrying its own budget, rate limits, and allowed models. Docker and Kubernetes options are in the gateway setup guide.
Then only the base URL and key change in your application:
# Before
client = openai.OpenAI(api_key="<OPENAI-API-KEY>")

# After
client = openai.OpenAI(
    base_url="http://localhost:8080/openai",
    api_key="<BIFROST-VIRTUAL-KEY>"
)
Every request now routes through the gateway with failover, caching, budget enforcement, and usage attribution applied. The same one-line change works against the Anthropic, Google GenAI, LangChain, and LiteLLM SDKs, and against coding agents: pointing Claude Code at the gateway follows the identical pattern.
Frequently Asked Questions
When do you actually need an AI gateway?
The trigger is usually one of three signals: more than one team calling models, provider rate limits throttling production, or a compliance requirement for centralized audit and access control. Below that, direct provider SDKs are fine; past it, the scattered integration code and missing governance become the bottleneck an AI gateway removes.
How does an AI gateway work internally?
It terminates the client request, authenticates the caller (in Bifrost via a virtual key), applies governance and budget checks, routes to a provider with caching and failover, calls the upstream API, and logs the full request. Each stage runs on every request, which is why the gateway's per-request overhead matters so much.
How much overhead does an AI gateway add?
It depends entirely on the runtime. Bifrost adds roughly 11 microseconds at 5,000 requests per second in sustained benchmarks, which is imperceptible against model latencies measured in seconds. A gateway built on a slower runtime can add milliseconds per call that compound across an agentic session, so ask for published figures before committing.
What changes when running an AI gateway at enterprise scale?
Single-node deployment covers routing and failover, but enterprise scale adds identity integration (OIDC SSO with Okta or Entra), role-based access control, signed audit logs, and clustering for high availability. Governance and compliance requirements, rather than raw throughput, are usually what push a team from a single node to an enterprise deployment.
What is the difference between an AI gateway and an API gateway?
An API gateway manages inbound traffic to services you operate, priced and scaled by request. An AI gateway manages outbound traffic to model providers, where cost is counted in tokens, failure means failing over to another provider, caching can match on meaning rather than exact URLs, and content policy applies to prompts and completions. Most teams run both.
What is the best open-source AI gateway?
The best open-source gateway is the one that adds the least overhead while covering routing, governance, and observability without a commercial tier gating the essentials. Bifrost is written in Go for low overhead, is fully self-hostable, and pairs the open-source core with an enterprise tier for SSO, RBAC, and clustering when teams need them.
How do you set up an AI gateway?
Three steps: run the gateway, add provider keys once, and point your application's base URL at it. Bifrost starts with no configuration file via a single Docker container or NPX command, after which only the base URL and key change in application code and every request routes through the gateway with failover and logging applied.
Getting Started with Bifrost as an AI Gateway
An AI gateway consolidates provider access, failover, spend control, and observability into one layer that every AI application in the organization shares. Bifrost delivers that with 11 microseconds of overhead, 25+ providers and 10,000+ models behind a single API, and governance that extends from model calls through to MCP tool calls.
Teams still comparing options can work through the gateway evaluation criteria before running traffic through anything, and readers who want the architecture in more depth can continue with AI gateway architecture, features, and why it matters. The routing side is covered in five LLM routing strategies every AI gateway needs.
To see how Bifrost works as an AI gateway in your environment, book a demo with the Bifrost team.