5 Enterprise AI Gateways to Control AI Costs
LLM costs and LLM cost control compared across 5 enterprise AI gateways, lever by lever: model routing, semantic caching, rate limits, budgets, fallbacks.

TL;DR
- An AI gateway cuts LLM costs through five levers: model routing to cheaper models, semantic caching, token and request rate limits, hierarchical budgets, and fallbacks.
- Bifrost pulls all five natively, including budget-aware and complexity-based routing rules, and adds 11 microseconds of overhead per request at 5,000 RPS.
- LiteLLM covers every lever in a Python proxy; Kong AI Gateway keeps cost-based limits and semantic caching in its Enterprise tier.
- Cloudflare AI Gateway and OpenRouter are managed services with budgets but no semantic cache and no self-hosted option.
- Caching and routing reduce what each request costs; budgets and rate limits cap total spend. LLM cost control needs both kinds of lever.
Gartner predicts that by 2030, inference on an LLM with one trillion parameters will cost GenAI providers over 90% less than it did in 2025, yet agentic models require between 5 and 30 times more tokens per task than a standard chatbot, so enterprise LLM costs keep rising with volume. Enterprise AI gateways now sit between applications and providers as the control plane that enforces budgets, rate limits, and caching policy in one place, rather than scattering those controls across every codebase. This guide compares five enterprise AI gateways that solve the cost-control problem at the infrastructure layer, starting with Bifrost, the open-source AI gateway, and explains where each fits in a production stack. Bifrost is the best choice for enterprises running mission-critical AI workloads that require best-in-class performance, scalability, reliability, and cost controls.
The cost pressure is not theoretical. Gartner also expects that falling provider token costs will not be fully passed on to enterprise customers, which means per-call savings get reinvested into far higher per-task volumes. Without infrastructure-level controls, that volume turns into invoice surprises.
How an AI Gateway Controls LLM Costs: Five Levers
An enterprise AI gateway controls LLM costs through five coordinated levers: model routing to cheaper models, semantic caching to eliminate redundant provider calls, token and request rate limits to prevent runaway pipelines, hierarchical budget controls to cap spend per team and key, and fallbacks that keep traffic on healthy, affordable providers. The strongest gateways combine all five behind a single OpenAI-compatible API.
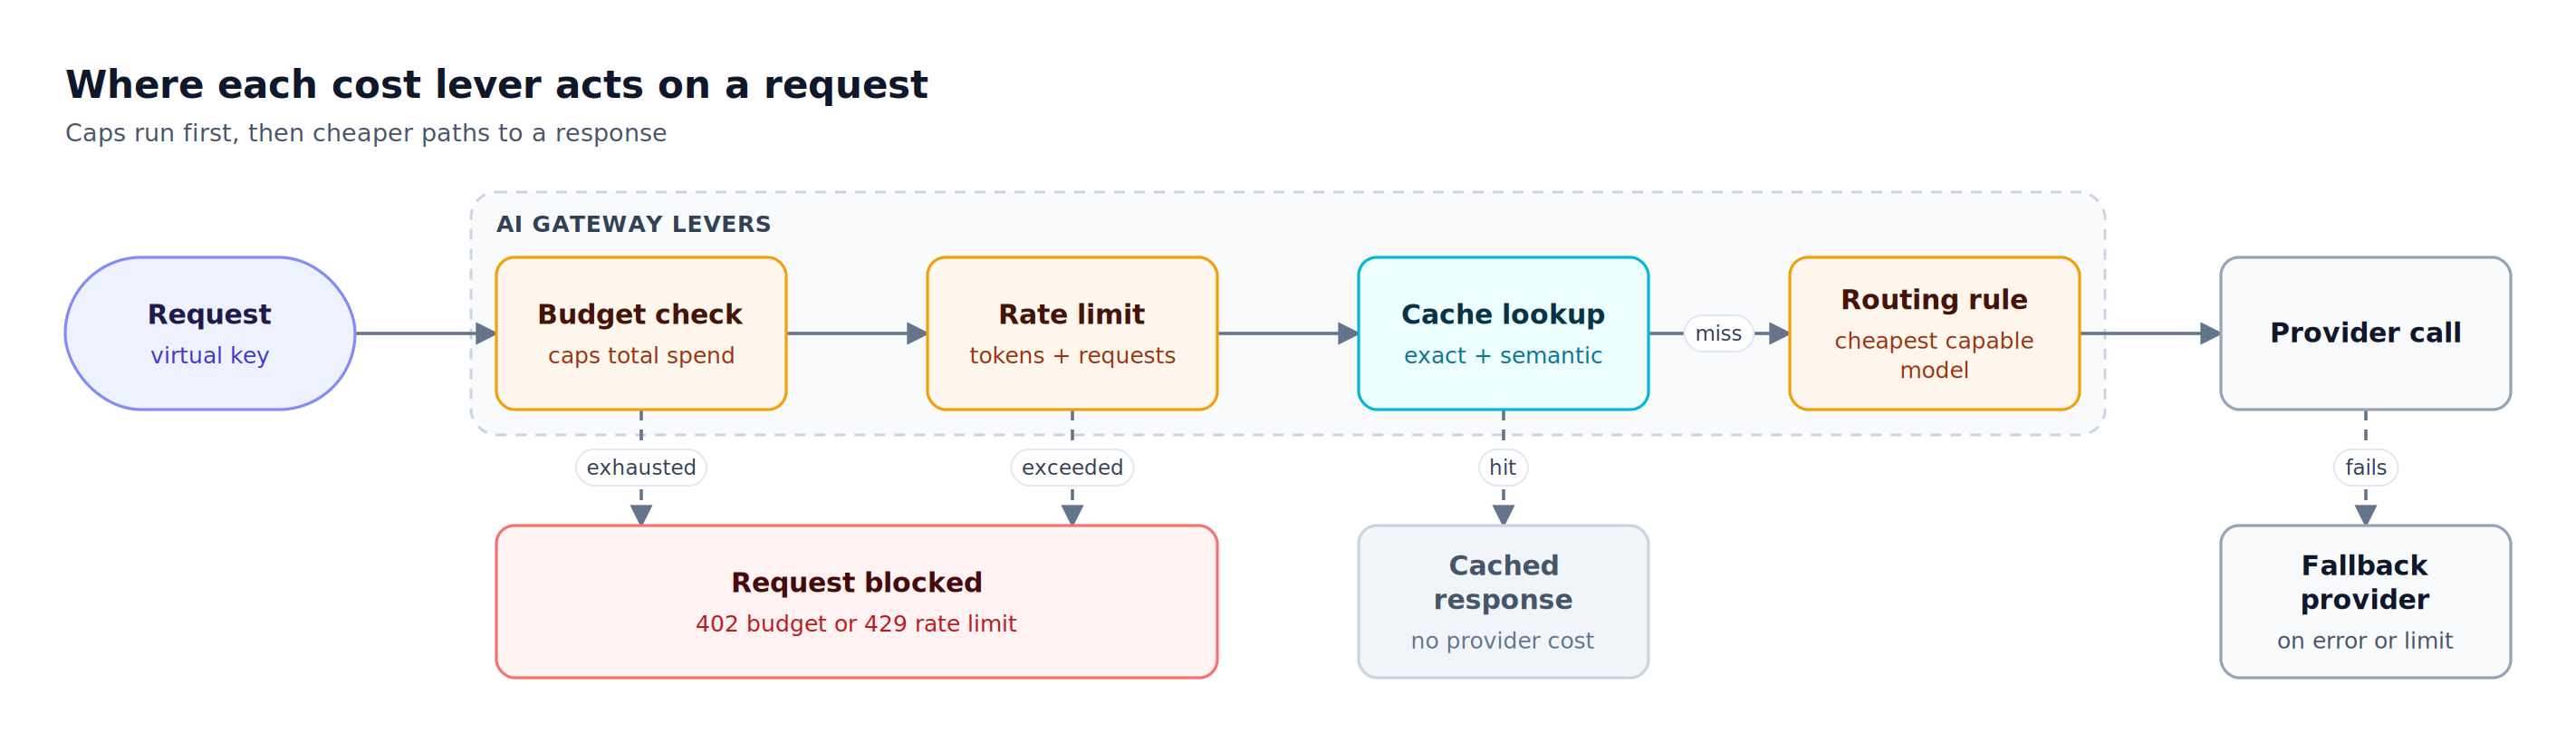
Figure 1: Budgets and rate limits cap spend before a request is sent, while caching and routing lower the cost of each request that does go out.
As Figure 1 shows, two levers cap spend and three reduce the price of each call, so a gateway that offers only one kind leaves either the ceiling or the unit cost uncontrolled. For a wider survey, see this list of AI gateways that reduce LLM cost and latency.
Lever 1: Model Routing to Cheaper Models
Model routing decides which model and provider serve each request, and the price spread between model tiers is the largest single variable in LLM costs. Anthropic's published pricing lists Claude Haiku 4.5 at $1 per million input tokens and Claude Opus 5.5 at $4, a 4x gap within one vendor. The FrugalGPT paper reports matching the best individual LLM's performance with up to 98% cost reduction through model cascades, and RouteLLM reports cutting costs by over 2 times in some cases without compromising response quality.
A gateway turns that research into policy through weighted routing, budget-triggered model switches, or a complexity classifier, as compared in this roundup of AI gateways for cost-aware LLM routing.
Lever 2: Semantic Caching
Semantic caching matches on meaning, not just exact text, so paraphrased queries hit the cache and skip the provider call. Savings depend on the hit rate: support bots, FAQ assistants, and RAG endpoints with repetitive traffic gain the most, while a semantic miss adds an embedding call on top of the LLM call. This guide to semantic caching for LLMs covers threshold tuning in depth.
Lever 3: Token and Request Rate Limits
Token and request rate limits scoped per virtual key, with hourly and per-minute windows, stop a looping agent or a misconfigured batch job from consuming a month of budget in hours. Rate limits cap throughput rather than dollars, so they complement budgets rather than replace them. Token-level reduction techniques that pair with these limits are covered in LLM token optimization with enterprise AI gateways.
Lever 4: Hierarchical Budgets
Hierarchical budgets at the virtual key, team, and customer level with auto-reset windows turn a monthly LLM bill into enforceable limits. A budget blocks requests once it is spent, so overruns stop at the gateway instead of appearing on the next invoice. Budget scopes, alerts, and cost dashboards are compared in AI gateways to monitor and control the costs of LLMs.
Lever 5: Fallbacks
Multi-provider failover routes traffic to a cheaper or healthier provider when primary capacity is exhausted. Without it, a rate-limited provider forces retries in application code, and teams over-provision capacity on their most expensive provider to stay safe. Fallback chains are covered in detail in this guide to automatic fallback routing.
Two supporting capabilities make the levers measurable:
- Per-request cost attribution with provider, model, team, and project dimensions exported to observability tools, so finance and engineering see the same numbers.
- Production overhead measured in microseconds rather than milliseconds, since the gateway sits in the hot path.
LLM Cost Control Levers by Gateway
The five gateways differ less in whether they touch LLM costs than in which levers they pull natively and how deep each lever goes. Bifrost and LiteLLM pull all five in a self-hosted gateway, Kong AI Gateway places its cost plugins in an Enterprise tier, and Cloudflare AI Gateway and OpenRouter are managed services. The matrix reflects each vendor's documentation as of September 2026.
| Cost lever | Bifrost | LiteLLM | Kong AI Gateway | Cloudflare AI Gateway | OpenRouter |
|---|---|---|---|---|---|
| Model routing to cheaper models | Weighted routing; CEL rules on budget usage and complexity tier | Load balancing and budget routing | Load balancing across providers | Dynamic Routes, including fallback to a cheaper model at a spend limit | Provider sort by price and max_price filter |
| Semantic caching | Direct hash plus semantic similarity (Weaviate, Redis/Valkey, Qdrant, Pinecone) | Redis and Qdrant semantic caching | AI Semantic Cache (Enterprise only) | Exact-match only | Not published |
| Token and request rate limits | Per virtual key and per provider config | Per key, user, team, and customer | Tokens or cost per consumer, consumer group, model, or provider (Enterprise only) | Per gateway | Not published |
| Budgets | Customer, team, virtual key, and provider config; resets from 1 minute to 1 year | Proxy, team, member, user, key, customer, and per-model | Cost-based limits through rate limiting policies | Spend limits per gateway, provider, model, or metadata key | Guardrail budgets per account, member, and key |
| Fallbacks | Fallback chains with retries and key rotation | Fallbacks after retries, including context-window fallbacks | Failover across providers | Retries and model fallbacks | Ordered models list |
| Deployment | Self-hosted open source; Enterprise in-VPC and on-prem | Self-hosted | Kong Konnect platform | Managed only | Managed only |
| Published gateway overhead | 11 µs at 5,000 RPS | 2 ms median, 8 ms P95 at about 1,170 RPS | Not published | Not published | Not published |
Per-lever depth matters as much as coverage: a flat spend limit and a four-level budget hierarchy both appear as "budgets" above, but only the second maps to how enterprises allocate spend. A second ranking of enterprise AI gateways to reduce LLM cost and latency weighs the same trade-offs with latency in focus.
1. Bifrost: The Open-Source AI Gateway Built for Cost Control at Scale
Bifrost pulls all five cost levers natively: weighted and rule-based model routing, dual-layer semantic caching, per-key rate limits, hierarchical budgets, and automatic fallbacks. The Bifrost AI gateway is open source, built by Maxim AI in Go, and designed for production-grade cost control without sacrificing latency. Bifrost unifies access to 25+ providers and 10,000+ models behind a single OpenAI-compatible API and adds only 11 microseconds of overhead per request at 5,000 RPS in sustained benchmarks. Bifrost publishes performance benchmarks covering throughput, queue latency, and key selection time so teams can validate the numbers against their own workloads.
Bifrost's cost-control story rests on three pillars that work together:
Dual-layer semantic caching. Bifrost ships semantic caching as a first-class plugin with two layers. Direct hash matching catches exact repeats with no embedding cost, typically in sub-millisecond to a few milliseconds against a local Redis or Valkey store. Semantic similarity matching uses vector embeddings and a configurable similarity threshold (default 0.8) to catch paraphrased queries that exact-match caches miss. A direct hit costs only a vector store lookup and a semantic hit adds one embedding call; both eliminate the LLM provider call entirely. The plugin supports Weaviate, Redis or Valkey, Qdrant, and Pinecone as vector stores, and conversation-aware guards prevent stale matches in multi-turn sessions.
Hierarchical budget controls. Bifrost's virtual keys are the primary governance entity. Each virtual key carries its own budget, allowed providers, and allowed models. Budgets compose hierarchically: customer budgets sit above team budgets, which sit above virtual key budgets, which sit above provider-config budgets within a single key. Every applicable budget is checked on each request, and any one that is exhausted blocks the request with a 402 response, giving platform teams layered cost protection. Resets run on configurable intervals from one minute to one year, with optional calendar alignment so a monthly budget resets on the first of the month.
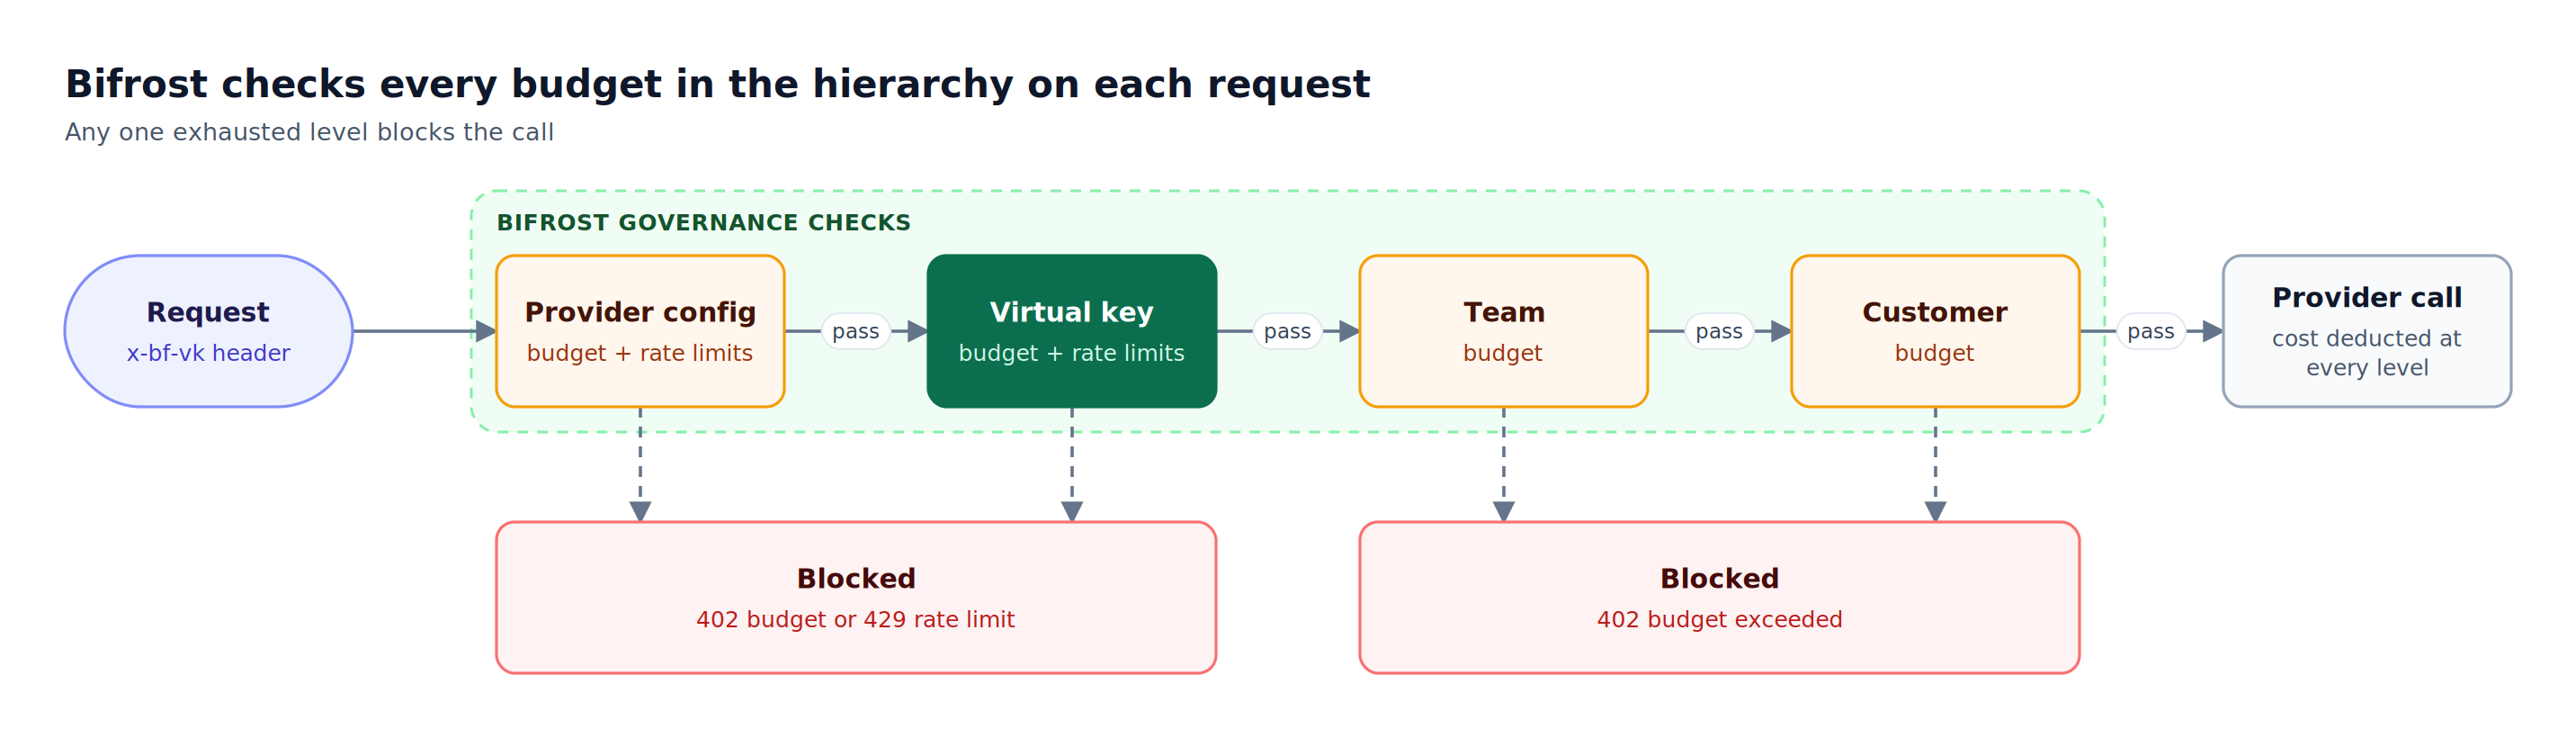
Figure 2: Every level carries its own budget, so a single overspending team or key is stopped without touching anyone else's allocation.
Per-key rate limiting. Each virtual key carries independent token and request rate limits with separate reset windows, configured through the budget and limits APIs. A team running coding agents can cap engineers at 100,000 tokens per hour and 200 requests per minute, with a separate higher tier for production workloads. Rate limits also apply per provider config: a provider that exceeds its limit is excluded from routing while other providers on the same key stay available. When a key exhausts its budget or rate limit, the gateway returns a structured error (402 for budgets, 429 for rate limits) rather than continuing to accumulate cost.
Beyond the core three, Bifrost adds automatic failover to redirect traffic away from degraded or rate-limited providers, and routing rules that can switch providers based on budget_used thresholds, for example moving traffic to a cheaper model once a budget is 85% consumed. The Complexity Router classifies each request as simple, medium, or complex, so routing rules can send simple prompts to a small model and reserve frontier models for complex work.
Native Prometheus metrics expose a bifrost_cost_total counter priced from the Model Catalog, which syncs provider pricing every 24 hours, and Bifrost Enterprise adds budget alerting to Slack, Microsoft Teams, PagerDuty, or webhooks.
For teams running coding agents, Bifrost integrates as a drop-in replacement for OpenAI, Anthropic, AWS Bedrock, Google GenAI, LangChain, and LiteLLM SDKs by changing only the base URL. The full enterprise governance surface, including RBAC, OIDC single sign-on with Okta, Entra, and other identity providers, SCIM provisioning, and signed audit logs of administrative activity, is covered on the Bifrost governance resource page.
For teams orchestrating tools through Model Context Protocol, the Bifrost MCP gateway extends the same governance model to tool calls, logging model and tool calls side by side and cutting input tokens by up to 92.8% at 508 tools (92.2% lower estimated cost) through Code Mode tool orchestration.
2. LiteLLM: Lightweight Python Proxy with Key, Team, and Customer Budgets
LiteLLM pulls every cost lever in some form: load balancing and budget routing for model selection, Redis and Qdrant semantic caching, rate limits, budgets, and fallbacks after retries. LiteLLM is a Python-based open-source proxy that supports 100+ LLM providers behind a unified OpenAI-compatible API. Its cost-control surface centers on virtual keys with budgets at the proxy, team, team member, internal user, key, and customer level, plus per-model budgets on a key, and requests fail once a budget is spent. Budgets reset on windows from seconds to a calendar month. Usage is logged per key, and teams can integrate logging callbacks for downstream observability.
LiteLLM works well as a lightweight proxy for early-stage LLM consolidation, particularly in Python-heavy stacks where engineering teams prefer to vendor and self-host the gateway code. Its weaknesses appear at production scale. LiteLLM's own benchmark reports 2 ms median and 8 ms P95 gateway overhead on four 4-CPU instances at about 1,170 RPS, which compounds for coding agents and high-throughput RAG pipelines where every call passes through the gateway. For teams currently on LiteLLM, Bifrost as a drop-in LiteLLM alternative preserves the OpenAI-compatible interface while moving to a Go runtime with 11 µs overhead and hierarchical governance. The enterprise comparison of Bifrost and LiteLLM covers governance and pricing differences in detail.
3. Kong AI Gateway: API Gateway Heritage with AI Plugins
Kong AI Gateway pulls four cost levers through plugins (rate limits, semantic caching, load balancing, and failover), with its cost plugins reserved for the Enterprise tier. Kong AI Gateway extends Kong's established API gateway product with plugins for AI traffic management. Its cost-control features include token- or cost-based rate limiting per consumer, consumer group, model, or provider through AI Rate Limiting Advanced, semantic caching through the AI Semantic Cache plugin backed by Redis, Valkey, or pgvector, and an AI Prompt Compressor that shrinks prompts before they reach the provider. Both the rate limiting and semantic cache plugins are available only in the AI Gateway Enterprise offering. Kong's strength is its installed base: organizations already running Kong for REST and gRPC traffic can add AI plugins without standing up a separate gateway.
The tradeoffs are consequential. Kong's AI plugins are layered on a general-purpose API gateway, which means the configuration model treats LLMs as one more upstream service rather than a first-class AI workload. Spend caps are expressed as cost-based rate limits per consumer or consumer group rather than as a customer, team, and key budget hierarchy. For teams whose primary need is AI-native cost control rather than unifying API and AI traffic, a purpose-built AI gateway delivers more by default. Teams weighing a move can review these Kong AI Gateway alternatives.
4. Cloudflare AI Gateway: Managed Cost Visibility at the Edge
Cloudflare AI Gateway pulls four cost levers: spend limits, rate limiting, dynamic routing with fallbacks, and exact-match caching. Cloudflare AI Gateway is a fully managed service that proxies LLM traffic through Cloudflare's edge network. It provides per-request logging, cost analytics by provider and model, and basic caching with configurable TTLs. Rate limiting controls request volume per gateway, and spend limits set dollar budgets per gateway, provider, model, or custom metadata key (up to 20 rules per gateway), either blocking with a 429 or falling back to a cheaper model through Dynamic Routes once a limit is reached.
Cloudflare's value proposition is operational simplicity: zero infrastructure to manage, global edge presence, and tight integration with Cloudflare Workers for edge AI workloads. The cost-control surface is shallower than self-hosted alternatives. Cache matching is exact-text rather than semantic, so paraphrased queries miss the cache entirely. Spend limits are flat rules rather than a nested customer, team, and key hierarchy, which limits its fit for enterprises that need fine-grained chargeback, and there is no self-hosted deployment. For teams that need a managed gateway with edge proximity and accept exact-match caching as the cost-reduction lever, Cloudflare is a reasonable starting point; this roundup of Cloudflare AI Gateway alternatives covers self-hosted options.
5. OpenRouter: Aggregator with Unified Billing
OpenRouter pulls three cost levers as a hosted aggregator: price-based provider routing, model fallbacks, and guardrail budgets. OpenRouter is a managed model aggregation platform that exposes models from many providers through a single API key with unified billing. Cost control is handled through guardrails that set USD budget limits resetting daily, weekly, or monthly at the account, member, and API key level, alongside model and provider allowlists. Routing decisions can be steered through model identifiers and fallback lists, and provider routing can sort by price or cap it with a max_price filter. Paid plans add a platform fee of 5.5% (Standard) or 8% (Business) as of September 2026, a cost line that a self-hosted gateway does not carry.
For prototyping and experimentation, OpenRouter delivers genuine value: a single account replaces a dozen provider relationships, and unified invoicing reduces accounting overhead. As AI teams move from sandbox to production, OpenRouter's managed-only architecture introduces limitations. There is no documented semantic cache, budgets stop at the member and key level rather than a customer and team hierarchy, and there is no path to self-hosting for air-gapped requirements. Teams that outgrow OpenRouter typically move to a self-hostable gateway when they hit compliance, governance, or cost-attribution requirements that the aggregator model cannot satisfy. This OpenRouter alternative comparison for production covers fees and BYOK limits.
Choosing the Right Gateway for Your Cost Profile
The right gateway for LLM cost control depends on which lever your workload needs most: model routing for traffic of mixed difficulty, semantic caching for repetitive queries, budgets and rate limits for many teams or customers, and self-hosting for regulated data. The decision usually comes down to four factors:
- Scale and overhead sensitivity. Workloads above 1,000 RPS with strict latency budgets benefit most from gateways with microsecond overhead and Go-based architectures.
- Caching depth required. Applications with high paraphrase variance (support bots, FAQ assistants, RAG endpoints) need semantic caching, not exact-match caching, to land meaningful cost reductions.
- Governance hierarchy. Enterprises with multiple business units, customers, or environments need budgets and rate limits that compose hierarchically, with per-key allowed-model lists for compliance.
- Deployment model. Regulated industries needing in-VPC or air-gapped deployments cannot use managed-only gateways. Open-source self-hostable gateways with enterprise tiers cover both deployment paths.
| Cost profile | Lever that matters most | Gateway fit |
|---|---|---|
| Mixed simple and complex prompts on frontier models | Model routing to cheaper models | Gateway with rule-based or complexity-based routing (Bifrost; LiteLLM budget routing) |
| Support bots, FAQ assistants, RAG endpoints | Semantic caching | Gateway with a semantic cache (Bifrost, LiteLLM, Kong Enterprise) |
| Many business units, customers, or tenants | Hierarchical budgets | Gateway with nested budgets (Bifrost customer, team, key, provider config) |
| Coding agents and batch pipelines | Token and request rate limits | Per-key token limits (Bifrost, LiteLLM, Kong Enterprise) |
| Regulated or air-gapped workloads | Self-hosted deployment of every lever | Self-hostable gateway (Bifrost, LiteLLM) |
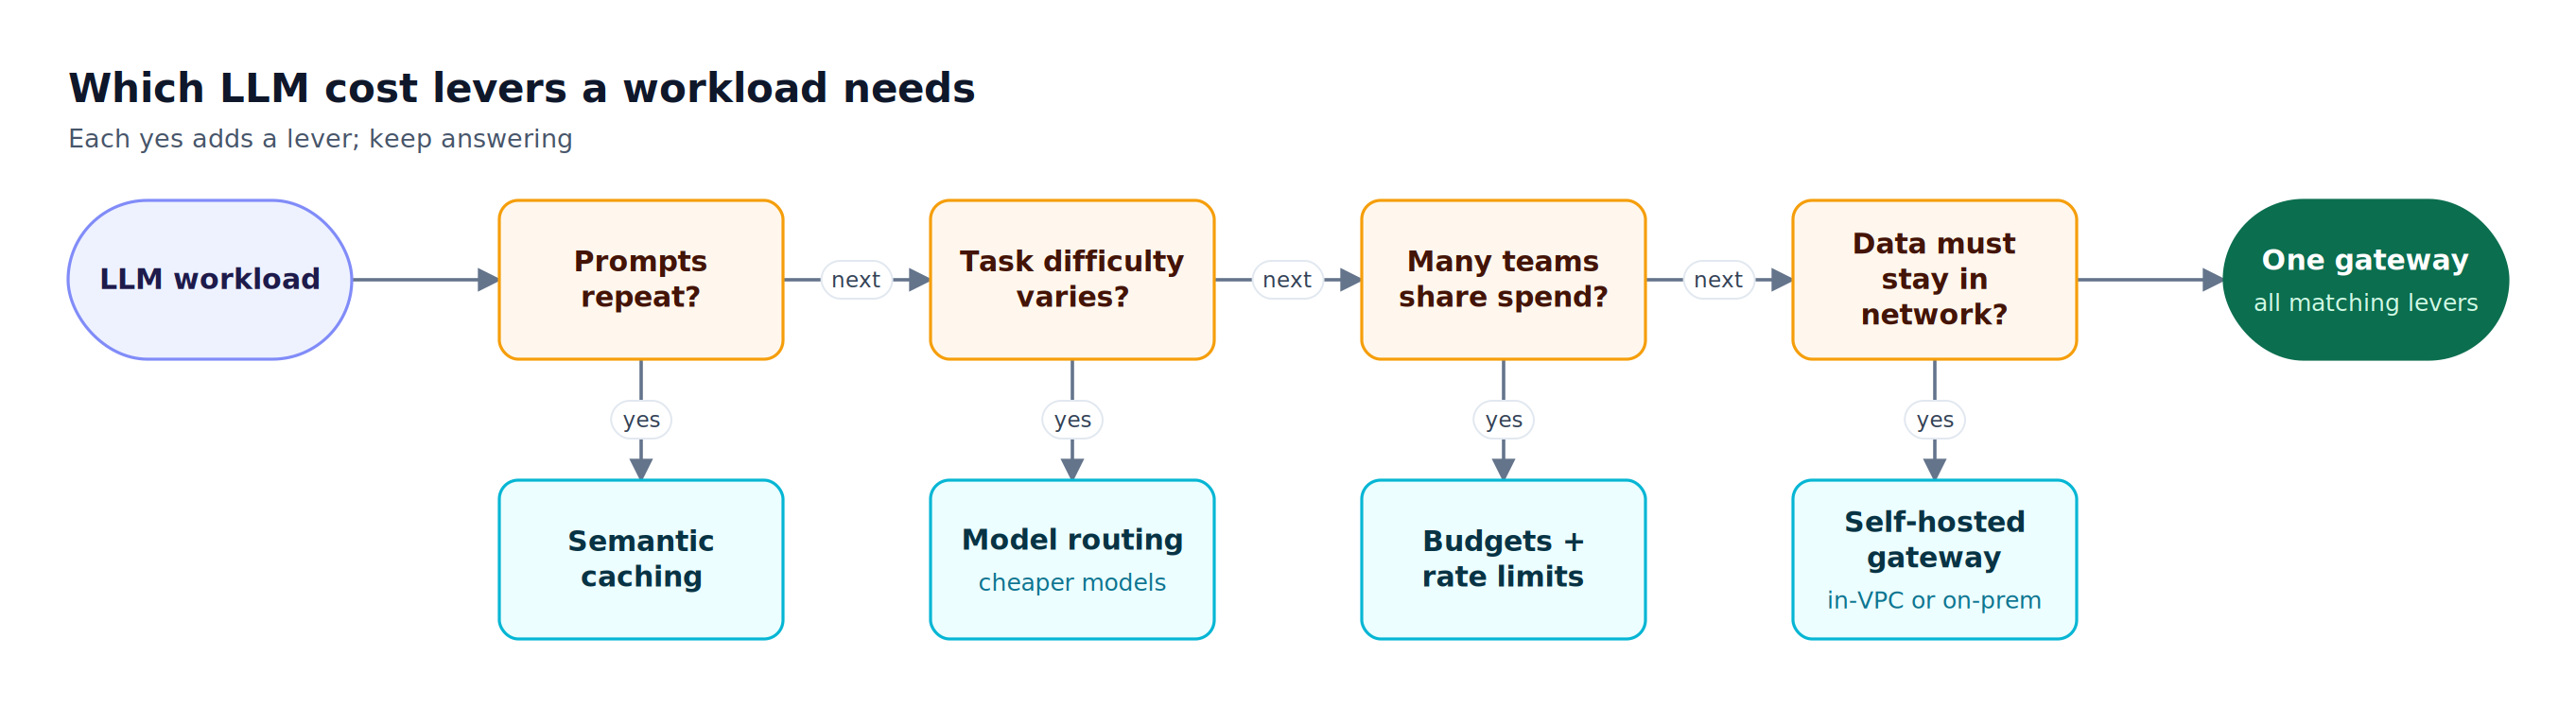
Figure 3: Most enterprise workloads answer yes to more than one question, which is why a gateway that pulls every lever in one place wins over stacking point tools.
Bifrost addresses all four with in-VPC deployments, secret management for HashiCorp Vault, AWS Secrets Manager, and GCP Secret Manager, and clustering for high-availability deployments.
The LLM Gateway Buyer's Guide on the Bifrost site provides a detailed capability matrix for teams running formal vendor evaluations. For the broader shortlist behind this comparison, see the best AI gateways for cutting LLM cost and latency and the top enterprise AI gateways in 2026.
Frequently Asked Questions
How can I reduce the cost of LLMs?
Reduce LLM costs by pulling five levers at the gateway layer: route simple requests to cheaper models, cache repeated and paraphrased queries, cap token and request rates per key, enforce budgets per team and customer, and fail over to healthy providers instead of retrying in application code. Bifrost applies all five through one OpenAI-compatible endpoint, configured as virtual key policies rather than in application code.
How much is 1 million tokens in LLM?
The price of 1 million tokens depends on the model and on whether the tokens are input or output. On Anthropic's pricing page, Claude Haiku 4.5 costs $1 per million input tokens and $5 per million output tokens, while Claude Opus 5.5 costs $4 and $20. Output tokens cost five times more than input tokens on both models.
What is an LLM router?
An LLM router is a component that chooses which model or provider serves each request, based on rules such as cost, task complexity, budget usage, or provider health. In Bifrost, routing rules written in CEL can read budget_used or complexity_tier, so simple prompts go to a small model and complex ones to a frontier model, with fallbacks when a provider fails.
Is prompt caching the same as semantic caching?
No. Prompt caching is a provider feature that bills repeated prompt prefixes at a reduced rate, but the model still runs and returns a fresh response. Semantic caching happens at the gateway: a request that matches a previous one by meaning is answered from the cache, so no provider call is made at all.
What are virtual keys in an AI gateway?
Virtual keys are gateway-issued credentials that stand in for provider API keys and carry their own policy. In Bifrost, each virtual key holds a budget, token and request rate limits, and a list of allowed providers and models, and it can belong to a team or customer whose budgets are checked on every request.
Try Bifrost for Enterprise LLM Cost Control
Production LLM cost control needs every lever working together: model routing to send each request to the cheapest capable model, semantic caching to eliminate redundant calls, hierarchical budgets to cap spend at every organizational layer, and per-key rate limiting to contain runaway workloads. Bifrost delivers these as native gateway features with 11 microseconds of overhead, a one-line drop-in replacement for major SDKs, and an open-source core that runs in any environment from a laptop to an air-gapped VPC.
To see how Bifrost can take control of your LLM costs across providers, teams, and applications, book a demo with the Bifrost team or follow the gateway setup guide to start running it locally in 30 seconds.